Join Us at Trusted Data Summit themed on "Trusted Data-AI Ready Outcome" on Nov 19th 2026 at 09:30 EST

DataOps Suite
The complete platform
Platform Overview
See how it works

DataOps Suite

Data Quality and Agentic AI platform that validates, reconciles, scores, monitors and remediates data from ingestion to BI and AI.

Why one platform

Agentic AI-powered test and rule creation
Agents generate data quality rules, validation tests and SQL from prompts, with your approval.
Data quality score per dataset
Shows the current score, what changed since the last run and the failing records behind it.
Validation and observability inside the pipeline
Every load is compared with its source, transformations are tested against business logic, and freshness, volume and schema changes are monitored.
Reports that match the source
Dashboard figures are compared with the source data behind them before users see them.
Test data without real records
Synthetic data that mirrors production replaces sensitive records in test environments.
Quality gates for releases
Pipeline and report changes are tested before they go to production.

Data Quality Monitor

Continuously profiles, validates and scores enterprise data, with Agentic AI that recommends rules and flags anomalies, so analytics and AI run on trusted data.

Capabilities

AI-recommended DQ rules and scoring
Agents suggest completeness, validity and uniqueness rules, with scores down to the column.
Data profiling
Analyzes distributions, patterns and frequencies to surface outliers.
AI-based observability
Agents monitor pipelines end to end, detect anomalies and suggest fixes.
Data catalog
Organizes models and tables in one catalog, with AI-drafted descriptions.
Data lineage
Traces data from origin to destination through every transformation.
Data quality issue tracking
Assigns every failing record to an owner and tracks it to resolution.

ETL Validator

Automates ETL/ELT testing, with Agentic AI that builds tests from mapping docs, confirming every record arrives complete, accurate and correctly transformed.

Capabilities

AI-generated ETL tests
Turns mapping docs into checks for joins, transforms and edge cases.
Source-to-target validation
Matches loaded data to the source, down to record counts and required fields.
Transformation validation
Verifies business logic with SQL, Python or Scala.
Migration validation
Checks schema, row counts and integrity for cloud migrations.
Metadata change audit
Catches schema and metadata discrepancies before they break pipelines.
Root cause and adaptive tests
Pinpoints where data broke, and agents update tests when mappings change.

BI Validator

Automates testing and governance for Power BI, Tableau and Oracle Analytics, with Agentic AI that builds tests from plain English and keeps reports accurate and reliable.

Capabilities

AI-created BI tests
Describe a test scenario in plain English, and agents build it.
Visual-to-source comparison
Compares the data behind every visual to the source using auto-generated SQL.
Regression and upgrade checks
Pixel-level comparisons across environments, with AI summaries of what changed.
Measure logic checks
Converts BI measures and calculations to SQL to confirm KPI logic.
Performance and load testing
Simulates concurrent users and measures load and refresh times.
BI governance
Finds unused measures, duplicate reports and orphaned tables.

Test Data Manager

Uses Agentic AI to detect and mask sensitive data and generate synthetic data that mirrors production, so teams can test without exposing real records.

Capabilities

AI synthetic data generation
Learns patterns from a small sample to create production-like data.
PII discovery and masking
Detects PII and PHI and replaces it with realistic fake values.
Relationship-aware data
Keeps linked tables connected with referential integrity.
Millions of records in minutes
Scales for load, stress and performance testing.
Multi-format output
CSV, Parquet or JSON, or loaded straight into test databases.
Compliant by design
Cloud or on-prem, supporting GDPR and HIPAA requirements.
Data Quality Use Case
The problem to solve
ROI calculator
Estimate the time and cost youโ€™ll save.
Financial services
SOX, BCBS 239 and NAIC MAR

Banking, Financial Services, and Insurance (BFSI)

Stop reporting errors before examiners find them, with every number traced from core system to board dashboard.

How Datagaps helps

Core platform migrations
Cut over banking and insurance platforms, including mainframe to cloud, without losing a record.
Regulatory reporting
Hold submissions until the data meets quality thresholds.
Financial reconciliation
Match GL to subledger automatically, with every break flagged.
Risk and credit data
Catch drift before risk, lending and pricing models degrade.
Dashboard attestation
Prove capital and board dashboards match the warehouse.

Healthcare

Keep claims and clinical data accurate through every migration, without exposing patient records in testing.

How Datagaps helps

EHR migrations
Confirm every record survives the move to Epic, Cerner or Oracle Health.
Claims data quality
Catch errors in claims and remittance feeds as they arrive.
APCD submissions
Check every file against state templates before you submit.
Clinical dashboards
Catch KPI and report changes after every refresh.
Provider directories
Keep provider listings accurate, current and audit-ready.

Life Sciences

Catch issues in clinical and real-world data before submission, and keep trial subject data out of test environments.

How Datagaps helps

Clinical data migrations
Move EDC, CTMS and LIMS data to the cloud without losses.
CRM migrations
Keep rebate calculations right through Veeva and Salesforce moves.
Pharmacovigilance data
Catch adverse event data issues before regulatory submission.
Commercial and clinical dashboards
Trace every KPI back to source clinical and lab records.
De-identified trial data
Keep subject data out of test, analytics and AI environments.

Manufacturing

Avoid broken ERP cutovers and supplier overpayments, and catch sensor drift before it hits production.

How Datagaps helps

ERP migrations
Move BOM, inventory and financial data across Oracle, SAP and cloud without breaks.
Supplier reconciliation
Catch overpayments and duplicate invoices with three-way PO, ASN and invoice matching.
Sensor data quality
Catch drift before it skews predictive maintenance and yield models.
Operations dashboards
Catch report breaks after every release or upgrade.
Safe ERP test data
Keep supplier pricing and production volumes out of lower environments.

Retail and Utilities

Catch settlement, inventory and pricing errors before your customers or regulators do.

How Datagaps helps

Settlement reconciliation
Match marketplace payout files to the general ledger, record by record.
Inventory accuracy
Keep POS, ERP and warehouse numbers in sync.
Pricing and promotions
Catch price and promotion mismatches across channels.
Reliability dashboards
Keep SAIDI and SAIFI reliability reporting accurate.
BI under load
Make sure reports hold up for thousands of concurrent users.

Higher Education & Research

Get enrollment, financial-aid and transcript data right before SIS cutover, before students feel it.

How Datagaps helps

SIS migrations
Validate moves from Banner or PeopleSoft to Workday Student or Ellucian.
Financial-aid reconciliation
Match aid and Bursar data to the general ledger.
Enrollment reporting
Keep census and admissions dashboards consistent from cycle to cycle.
Federal reporting
Monitor data quality ahead of IPEDS submissions.
Safe student data
Test and train AI without exposing real student records.

Trusted Data Summit

A practitioner summit focused on the validation, observability, governance, and reconciliation practices that determine whether enterprise data is ready for AI.

Save Your Spot
Nov 19th, 2026
Technology Partners
Cloud, data and BI platforms

Become a partner

Resell, implement or co-deliver

Technology Partners

Datagaps works natively with the cloud, data and BI platforms your teams already run.

Our technology partners

AWS logo
Cloudera logo
Tableau logo
Microsoft Azure logo
Snowflake logo
Oracle logo
Databricks logo

SI Partners

Consulting and integration firms that deliver Datagaps validation for enterprise clients worldwide.

Our SI partners

Solutions

Use cases

Cloud platforms

BI and analytics

What Is Data Profiling in ETL? Types, Best Practices & Tools

Data Profiling in ETL
Listen to article 0:00 / 5:35

Key Takeaways:

  • Data profiling analyzes source data characteristics before transformation and loading in ETL pipelines.
  • Five key types: structure, content, relationship, column, and pattern profiling.
  • Profiling at the source catches data quality issues before they propagate downstream.
  • Datagaps ETL Validator automates profiling as a native capability within the test workflow.

According to Gartner, inconsistency in data across sources is the most challenging data quality problem organizations face. Data profiling at the source catches these issues before they propagate.

What is data profiling in ETL?

Data profiling is a critical process in data management, particularly in ETL (Extract, Transform, Load) and data quality management. Profiling enables businesses to understand the structure, content, and quality of data within their systems. In this article, weโ€™ll explore the role of data profiling in ensuring data quality, delve into various types of data profiling, best practices, and share examples to illustrate its importance. 

What does data profiling achieve?

Data profiling assesses data for quality, consistency, and suitability before it moves through ETL pipelines. In an ETL context, profiling helps data engineers identify data anomalies, missing values, duplications, and outliers early, allowing them to make corrections and adjustments in the ETL process itself. The primary objectives of data profiling are: 

  • Assessing Data Quality: Uncover inconsistencies, incomplete data, or duplicate records to improve data quality. 
  • Data Transformation Guidance: Help determine what transformations (cleansing, standardization) are needed before data is integrated or loaded. 
  • Understanding Data Structure: Identify the relationships, dependencies, and structures within datasets for better schema design and metadata management. 

Gartner predicts 70% of new applications will use low-code/no-code platforms by 2026, accelerating the shift toward automated profiling tools .

What Are the Different Types of Data Profiling?

1. Column Profiling:

This involves analyzing each column in a dataset to determine basic metrics like minimum, maximum, mean, median, and standard deviation. It identifies characteristics such as data type, value distribution, and the presence of null values. 

Example: Consider a customer_age column in a customer database. Column profiling might reveal the following: 

Metric 

Value 

Min Value 

18 

Max Value 

75 

Null Count 

12 

Data Type 

Integer 

Such metrics help identify if customer_age has unexpected nulls or invalid data types. 

2. Data Type Profiling:

Involves checking if the data in each field aligns with the expected data type (e.g., integer, text, date). This is essential in ETL to ensure transformations operate on consistent data types, reducing errors in data manipulation. 

Example: In a transaction table, a transaction_date column should have only date data types. Data type profiling would flag any string values mistakenly entered. 

3. Pattern Profiling:

Analyzes data for patterns within values. This is particularly useful for fields like phone numbers, social security numbers, or email addresses, where values should follow specific formats. 

Example: An email column in an employee dataset could use pattern profiling to confirm that all entries match a regular expression pattern like [a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,6}. Pattern profiling can flag entries that do not match, helping cleanse invalid emails from the dataset. 

4.Dependency Profiling:

Examines relationships and dependencies between columns to understand correlations. This helps verify if certain fields are dependent on others, which can be crucial for relational integrity. 

Example: In a customer orders dataset, order_total might be expected to be a sum of individual product prices in a given order_id. Dependency profiling helps confirm if this assumption holds. 

5.Uniqueness and Duplicate Profiling:

Focuses on identifying duplicate or unique values within a dataset. This is essential in ETL workflows to ensure accurate, duplicate-free records in data warehouses. 

Example: A customer_id column in the customers table should ideally contain unique values to ensure customer data integrity. 

Profiling Type What It Examines Example Output When to Use
Structure Schema, data types, constraints Column count, nullability Initial source assessment
Content Value distributions, ranges Min/max, cardinality Pre-transformation validation
Relationship Cross-column dependencies FK integrity, referential links Multi-table pipelines
Column Per-column statistics Uniqueness %, null %, patterns Data quality baselining
Pattern Format and regex matching Date formats, phone patterns Compliance-sensitive fields

What Are the Best Practices for Data Profiling in ETL?
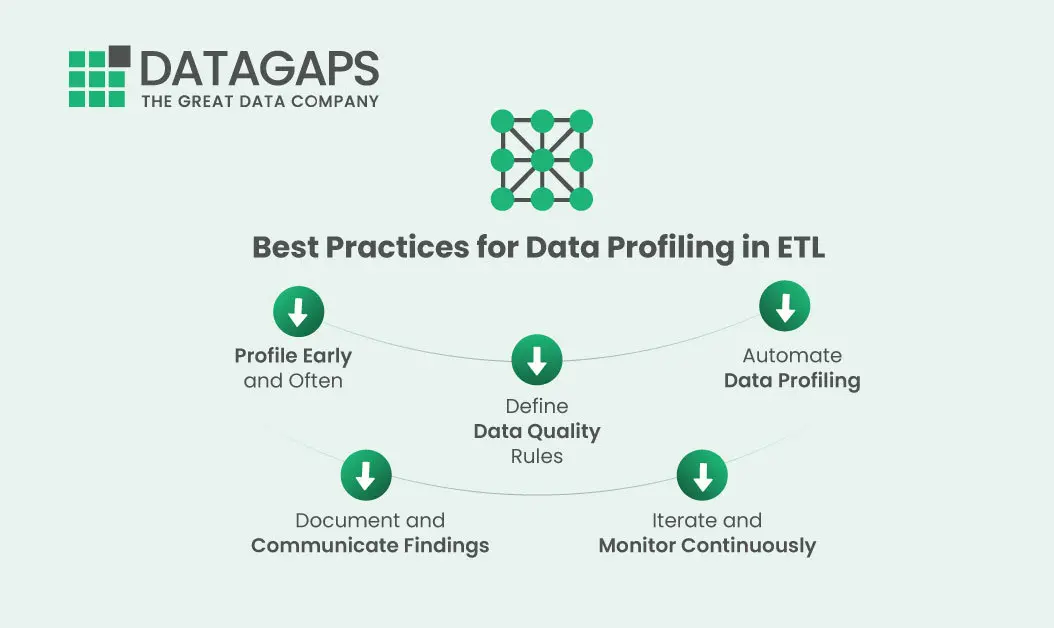
Best Practices for Data Profiling in ETL

1. Profile Early and Often

Integrate profiling at multiple stages in the ETL process to identify and correct quality issues at the source, during transformation, and before loading. Profiling early minimizes downstream errors. 

2. Define Data Quality Rules

Establish rules that define what constitutes quality data, such as acceptable ranges for numerical data, mandatory field presence, and consistent data types. These rules should guide your profiling and help standardize data across sources. 

3. Automate Data Profiling

Datagaps ETL Validator provides automated data profiling as a native capability within the ETL test workflow โ€” generating column statistics, pattern analysis, and relationship detection without separate tooling.

4. Document and Communicate Findings

Profiling generates valuable insights that should be shared with all data stakeholders. Documenting profiling results can inform downstream teams about data health, enhancing data governance. 

5. Iterate and Monitor Continuously

As data evolves, continuous profiling and monitoring are essential to maintain data quality. Scheduling regular profiling checks enables proactive detection and resolution of emerging issues. 

Datagaps ETL Validator provides automated data profiling as a native capability.

Frequently Asked Questions

1)What is data profiling in ETL and why is it important?
Data profiling analyzes source data characteristics โ€” types, patterns, distributions, relationships โ€” before it enters the ETL pipeline. It catches quality issues early, preventing bad data from corrupting transformations and downstream reports.
2)What is the difference between data profiling and data validation?
Profiling examines what data looks like (structure, patterns, statistics). Validation checks whether data meets predefined rules (nulls, ranges, business logic). Profiling typically happens first; validation runs continuously.
3)Can data profiling be automated in ETL pipelines?
Yes. Datagaps ETL Validator automates data profiling as part of the test execution workflow, generating column-level statistics, pattern analysis, and anomaly flags without manual SQL or scripting.
4)How often should data profiling be performed?
At minimum during initial source onboarding and before major migrations. For production pipelines, automated profiling should run with each data refresh cycle to detect drift in source data characteristics.
5)What are the most common data quality issues uncovered by profiling?
Null values in mandatory fields, inconsistent date formats, unexpected cardinality (duplicate keys), orphan records with no parent reference, and data type mismatches between source and target schemas.
Get Started Today

Talk to a datagaps expert

Anshul Agarwal
Anshul Agarwal

Director, Marketing, Datagaps

Director of Marketing at Datagaps. Brings hands-on experience across the data industry and data products to how Datagaps positions DataOps and validation.

Established in the year 2010 with the mission of building trust in enterprise data & reports. Datagaps provides software for ETL Data Automation, Data Synchronization, Data Quality, Data Transformation, Test Data Generation, & BI Test Automation. An innovative company focused on providing the highest customer satisfaction. We are passionate about data-driven test automation. Our flagship solutions, ETL Validator, DataFlow, and BI Validator are designed to help customers automate the testing of ETL, BI, Database, Data Lake, Flat File, & XML Data Sources. Our tools support Snowflake, Tableau, Amazon Redshift, Oracle Analytics, Salesforce, Microsoft Power BI, Azure Synapse, SAP BusinessObjects, IBM Cognos, etc., data warehousing projects, and BI platforms.  Datagaps

Related Posts:
ร—