AI-assisted data quality rule generation in Datagaps is a prompt-driven workflow that creates validation rules, including rule names, descriptions, quality dimensions and SQL logic, for selected Microsoft Fabric tables and columns, then executes them to produce column-level DQ scores, pass/fail results and sample bad records.
Key Takeaways
- Successful Fabric pipelines do not guarantee output trustworthy enough for reporting, operations and AI use cases.
- Defining checks manually across hundreds of tables and thousands of columns is hard to standardize and sustain.
- Datagaps generates rules from selected columns plus a generic prompt and a business-specific domain prompt.
- Each AI-generated rule includes SQL logic and dimension mapping and should be reviewed before execution.
- Results show column-wise DQ scores, rule pass/fail outcomes, sample bad records and an overall run summary.
To generate data quality rules for Microsoft Fabric at scale, connect Fabric as a data source in Datagaps, create a data model over the tables you want to validate, and use the Data Rules Wizard’s AI-assisted mode to generate rules from your selected columns and prompts. You then review the rules, run validations and use the DQ score and bad-record samples to prioritize remediation.
Why does data quality matter once Microsoft Fabric pipelines are running?
As organizations adopt Microsoft Fabric to modernize analytics and accelerate AI-driven use cases, the focus quickly shifts from pipeline execution to outcome reliability. Pipelines may run successfully, but the real question is whether the output is trustworthy enough for reporting, operations, and AI experiences.
This becomes even more important when Fabric data powers automated dashboards and natural language use cases such as text to SQL. In these scenarios, quality issues can silently propagate and impact decisions at scale.
Datagaps helps address this by providing a structured workflow for data quality and validation, including AI-assisted rule generation to accelerate coverage and improve consistency.
Why is data quality rule generation difficult in Fabric environments?
Rule generation is difficult because enterprise data estates often include hundreds of tables and thousands of columns, each with business meaning and validation expectations. Defining and maintaining tests manually across that footprint is time-consuming, difficult to standardize, and hard to sustain as schemas evolve.
Many projects follow layered architectures across environments like DEV, STG, and PROD. Data changes at each layer due to ingestion and transformations. To maintain trust, teams typically need validation at table level and column level, and sometimes across layers.
A typical gold layer might include dozens of tables with dozens of columns per table. Common checks include:
- Numeric constraints such as revenue greater than zero
- Format checks such as valid email patterns
- Null checks for required attributes
- Uniqueness checks to prevent duplicate keys
- Cross-table consistency checks to ensure reconciliation across datasets
Manually implementing these checks at scale can become difficult to manage, especially when new columns appear and business logic changes.
How do you generate and validate data quality rules for Microsoft Fabric in Datagaps?
The end-to-end workflow has ten steps: connect Fabric, open the Data Quality section, build a data model, baseline the DQ score, create rules with the Data Rules Wizard, generate them with AI, scope them with prompts, review them, run validations, and interpret the results.
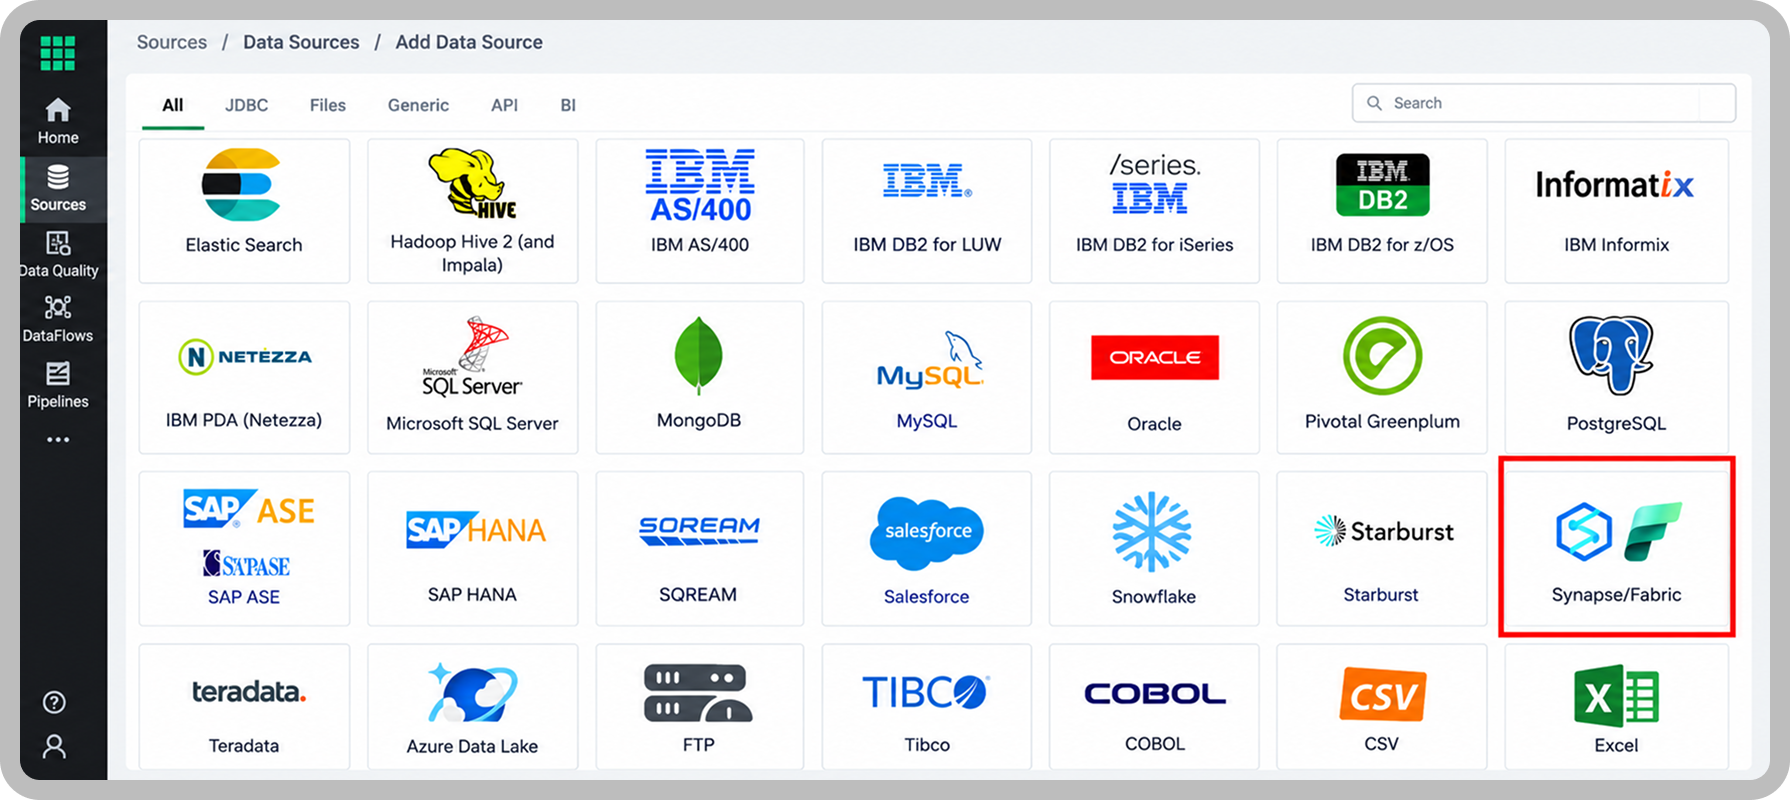
Step 1: Connect Microsoft Fabric as a data source
Start by adding Microsoft Fabric as a data source in Datagaps using the available connectors and the integration flow.
Step 2: Move to the Data Quality section to access DQ capabilities
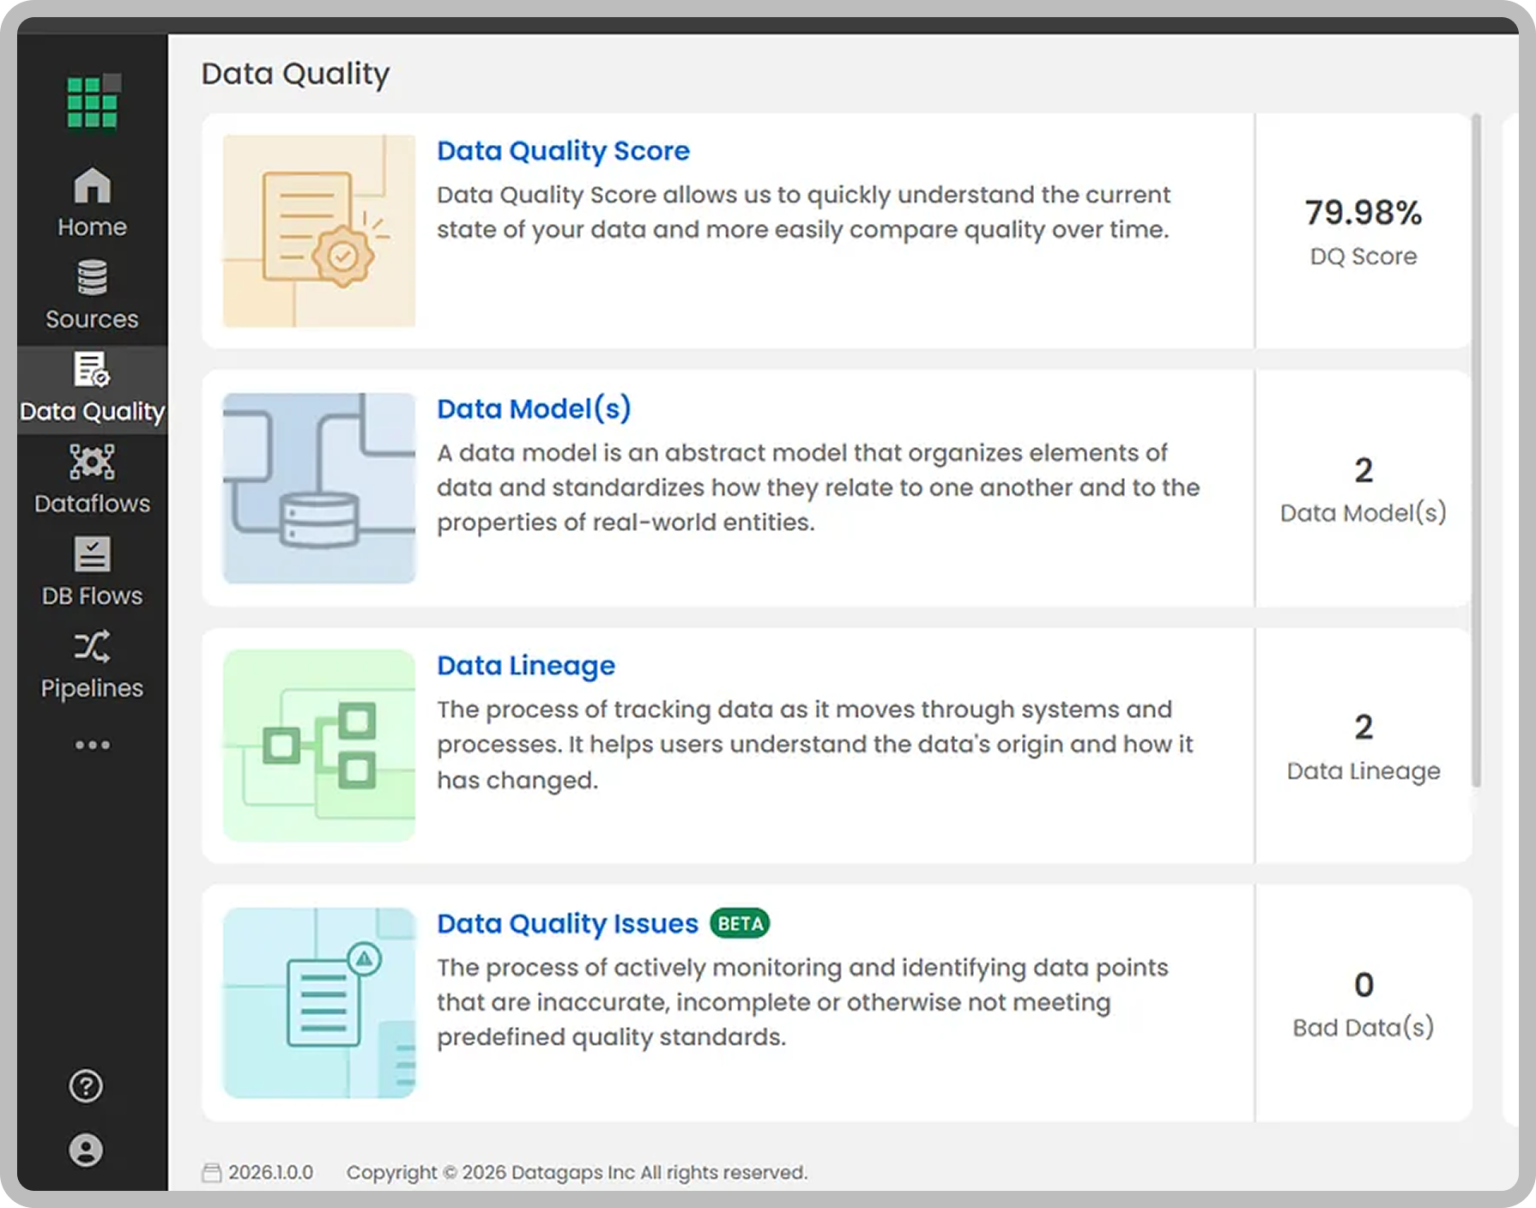
After the Fabric integration is set up, move to the Data Quality section in Datagaps. This area provides multiple data quality related capabilities, such as:
- Viewing and generating a Data Quality Score
- Exploring Data Lineage
- Reviewing data quality issues and related artifacts
This step is important because it is where you begin the quality workflow before building rules.
Step 3: Create a data model and select tables
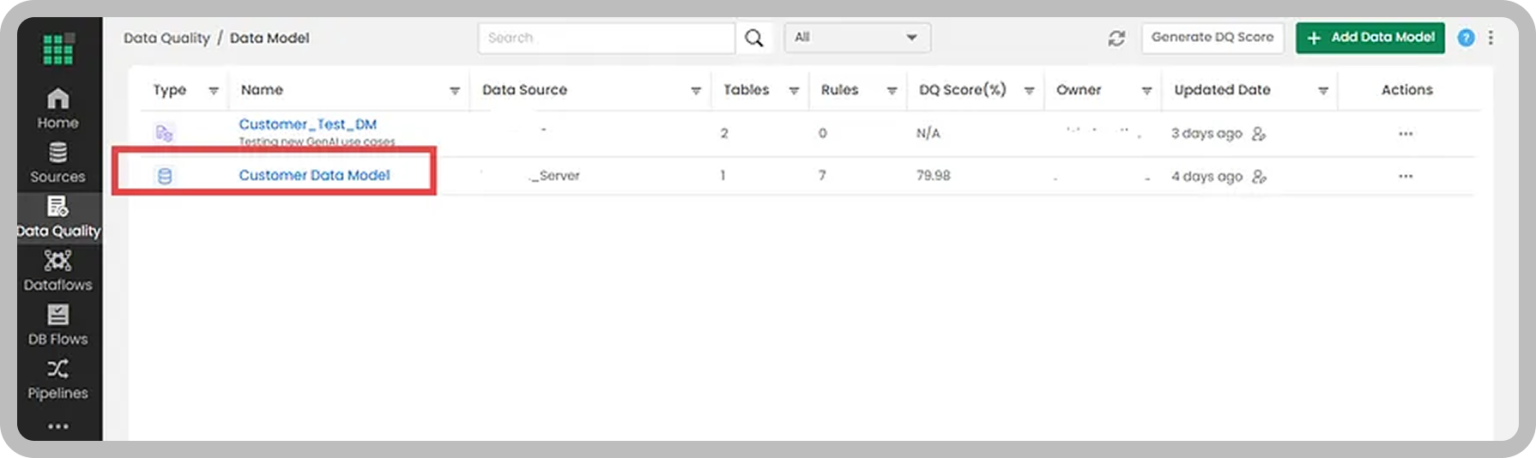
Create a data model as the base layer on which rules are generated and executed. Select the Fabric tables you want to validate. This can scale from a single table to hundreds depending on your scope.
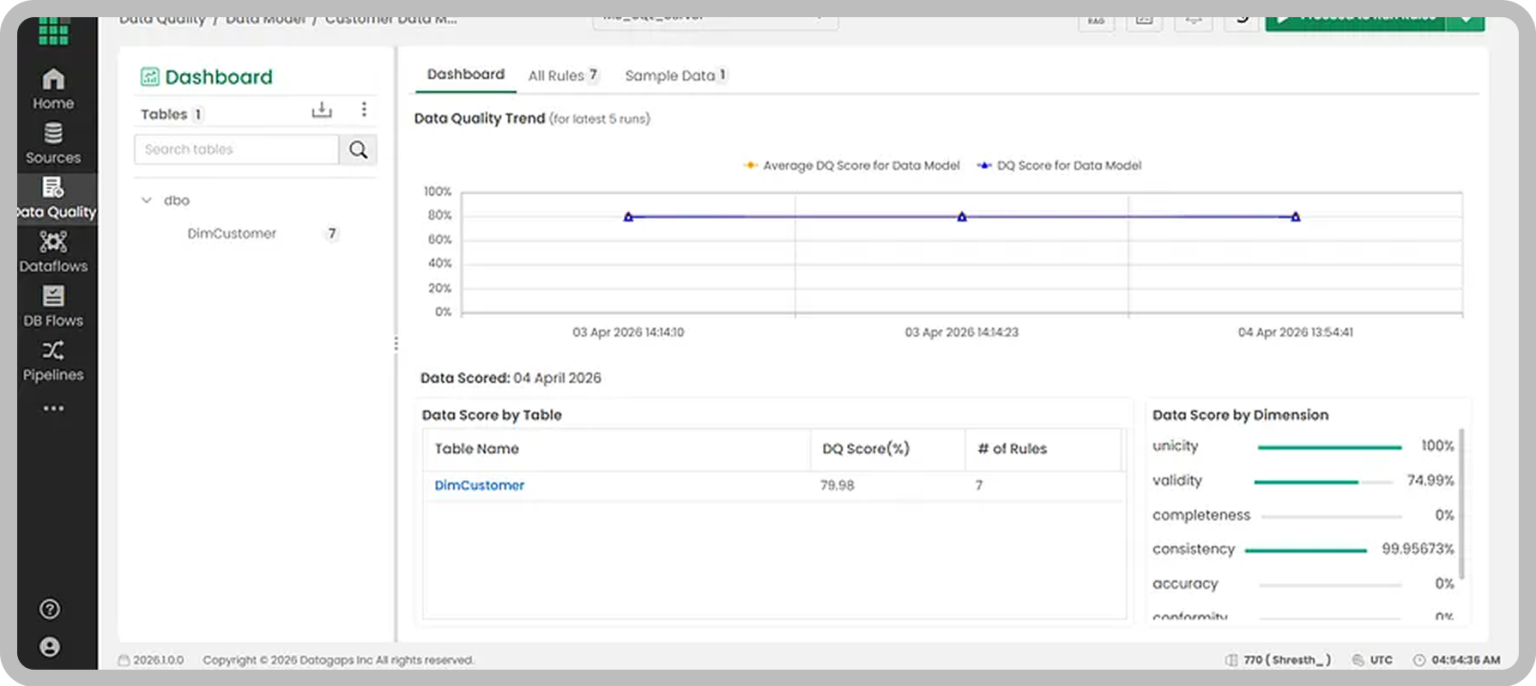
Step 4: Generate and review baseline DQ score and trends
Once the data model is set up, generate the DQ score to establish a baseline. Review trends and drilldowns to understand quality distribution across tables and dimensions.
Step 5: Create rules using the Data Rules Wizard
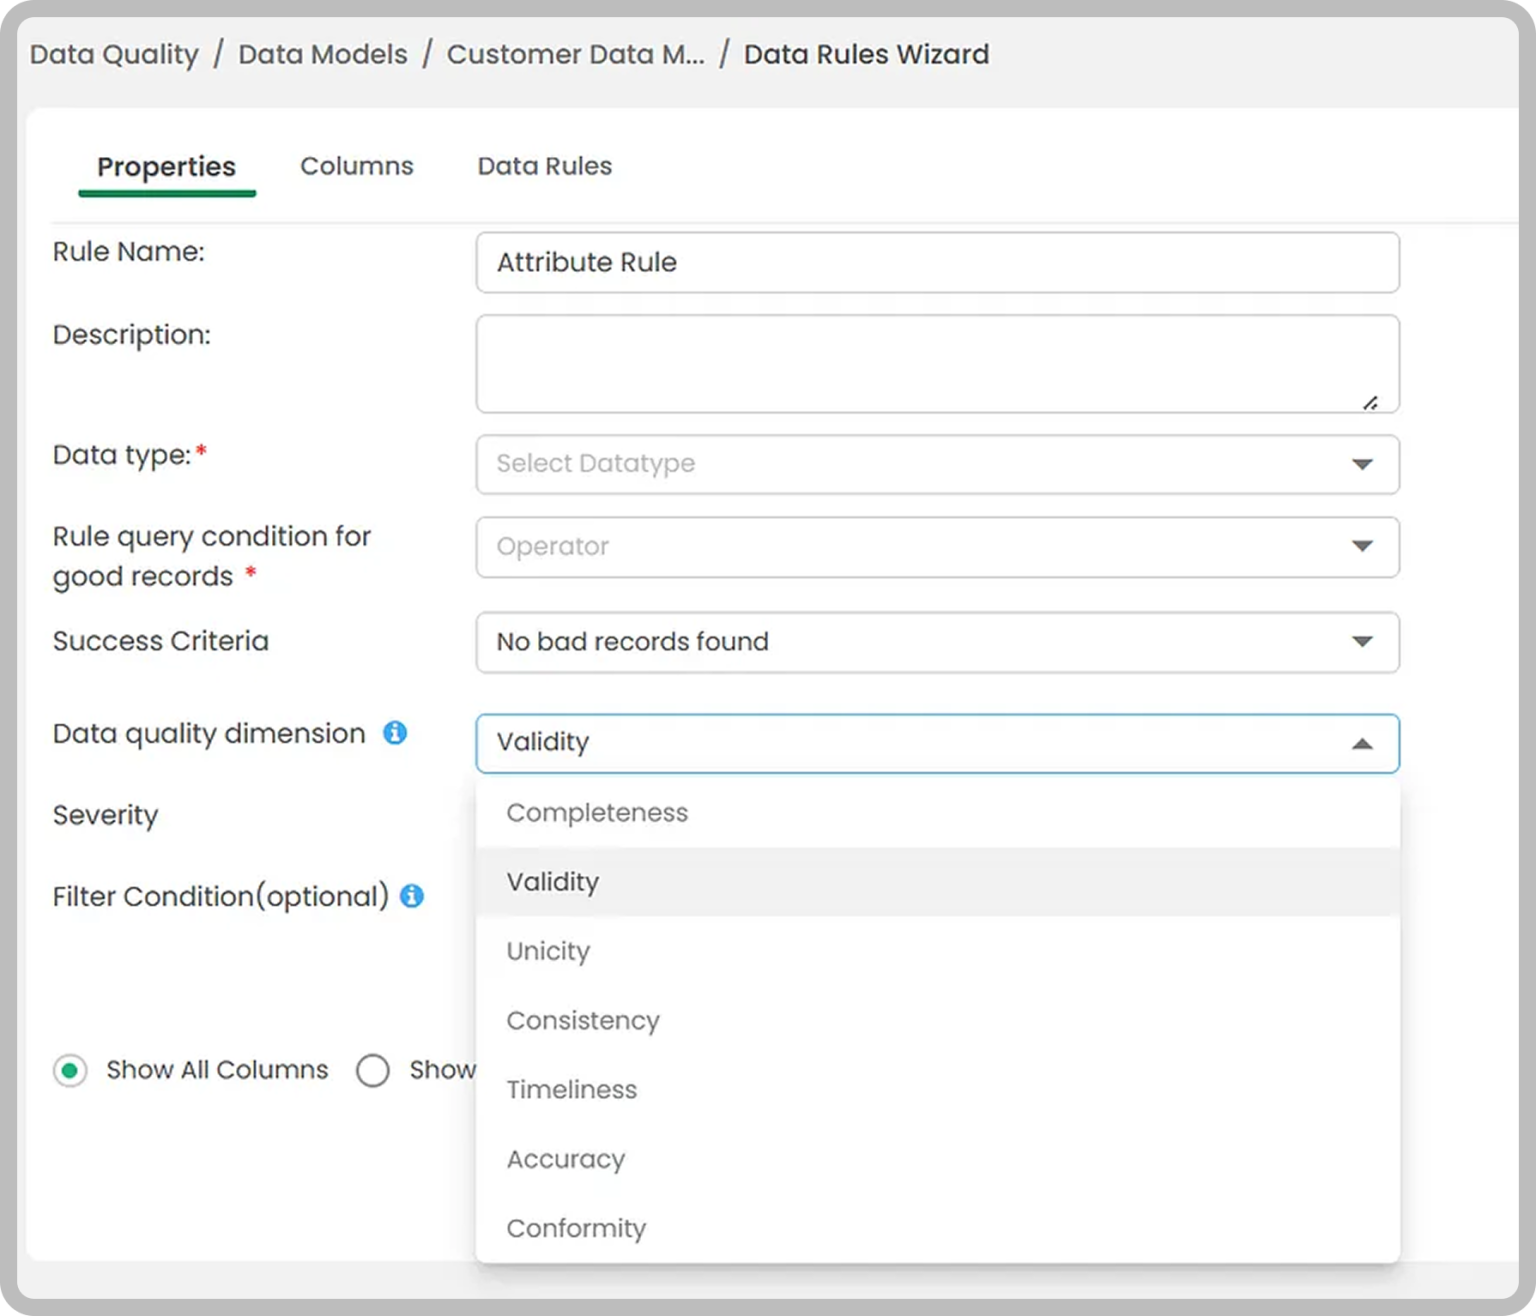
Datagaps provides a Data Rules Wizard that supports both manual rule definition and AI-assisted rule generation.
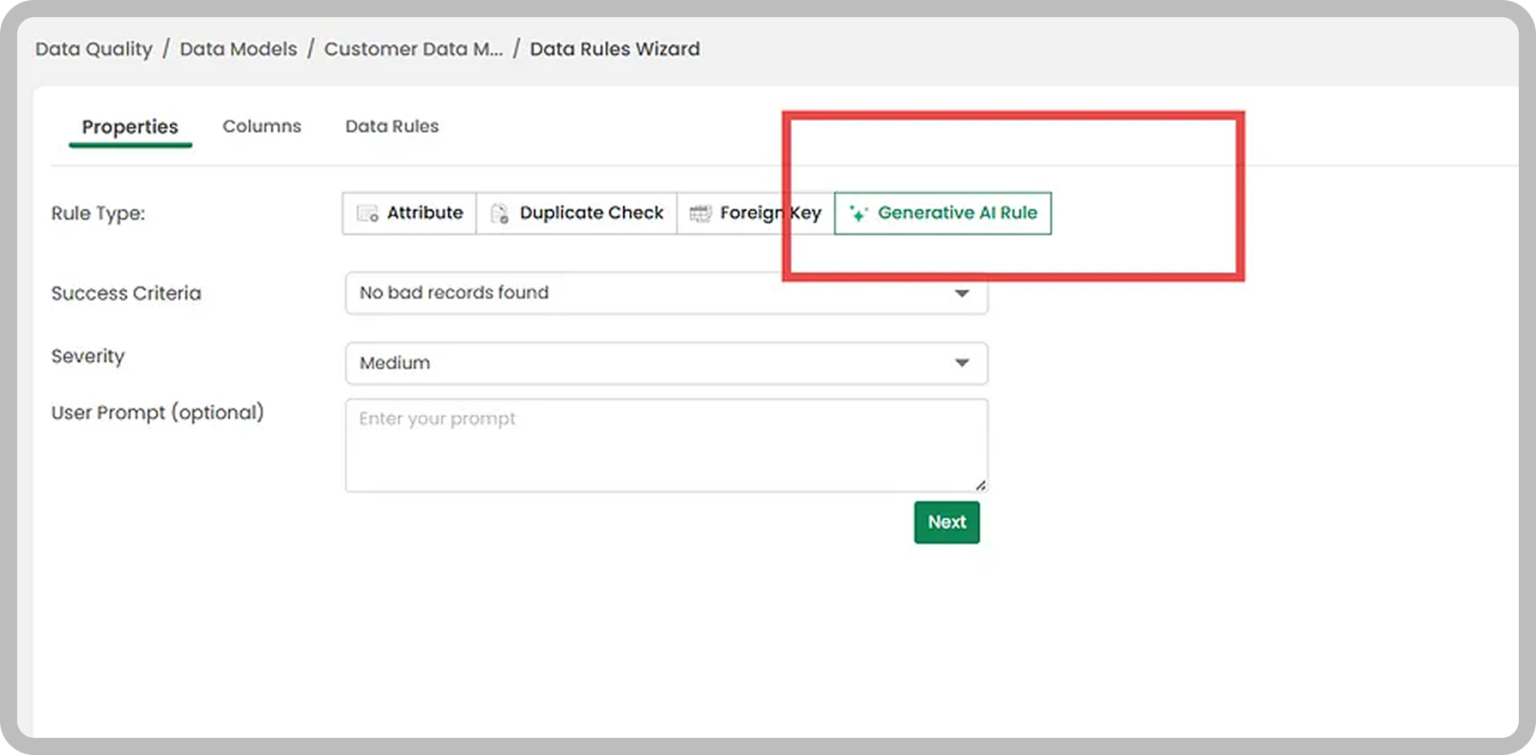
Step 6: Use AI-assisted rule generation to accelerate rule creation
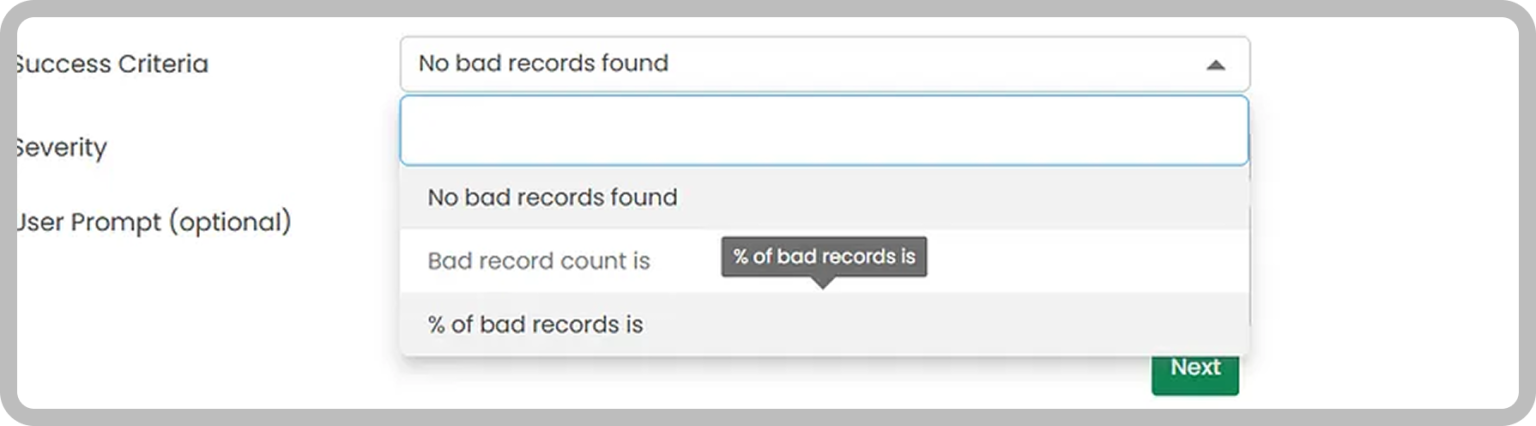
Switch the rule type to the AI-assisted mode and define execution criteria like success conditions and severity. This enables Datagaps to generate rule suggestions based on your selected columns and the prompt you provide.
Step 7: Select tables and columns, then provide prompts
Select the table and columns to include in rule generation. Use two prompts to improve output quality:
1. A generic prompt covering standard validations across most columns
2. A domain prompt covering business specific rules for critical fields
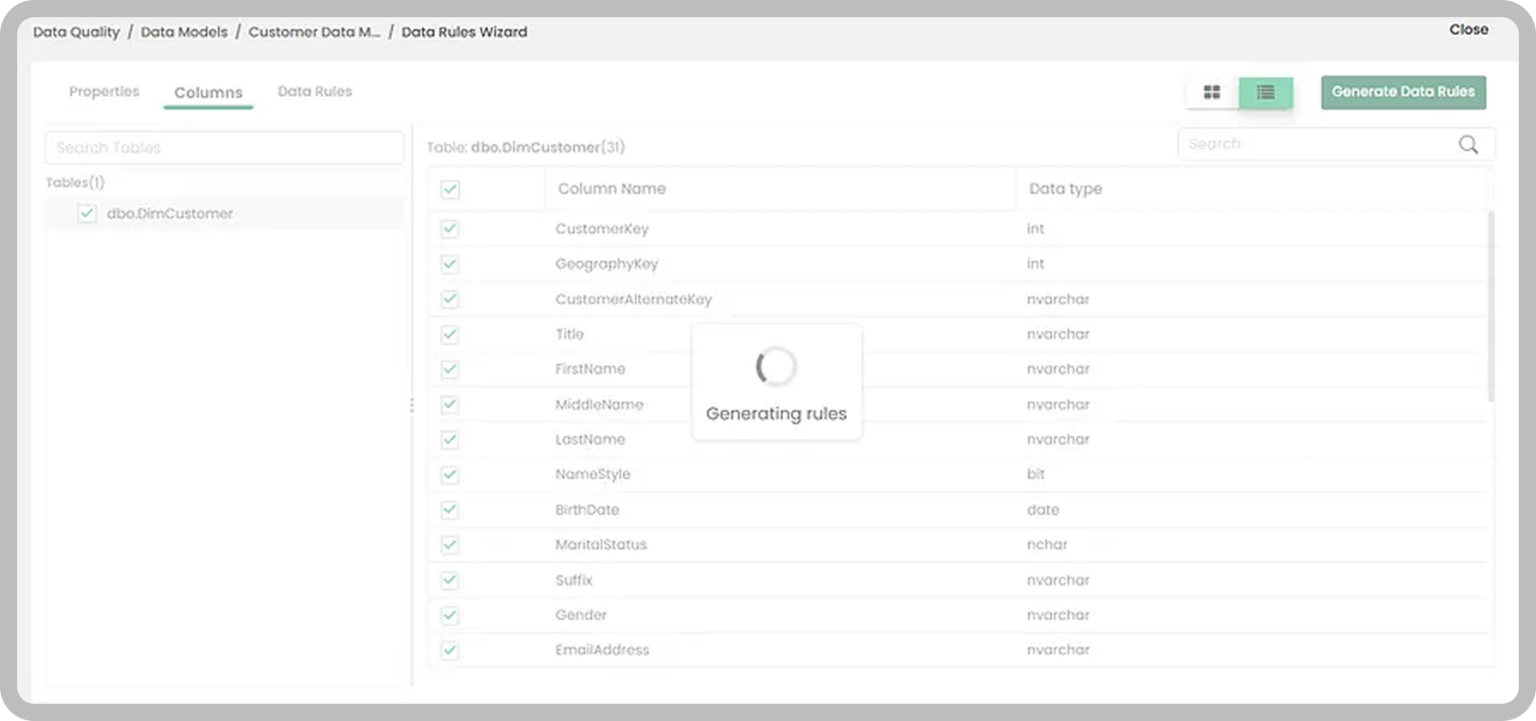
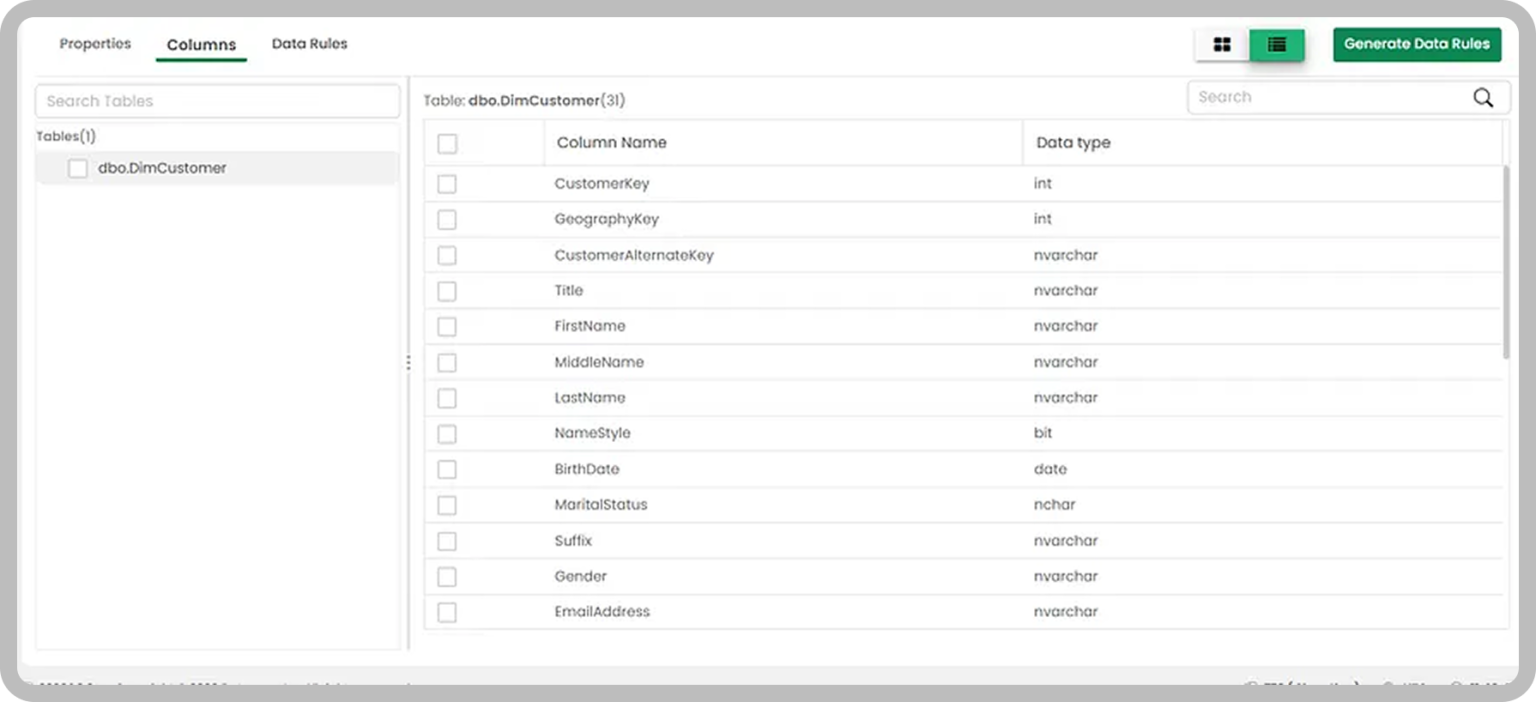
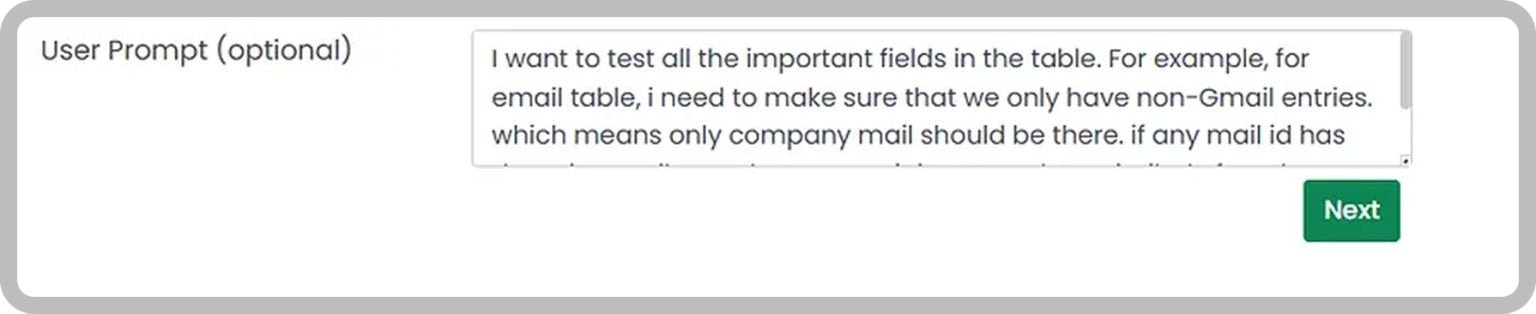
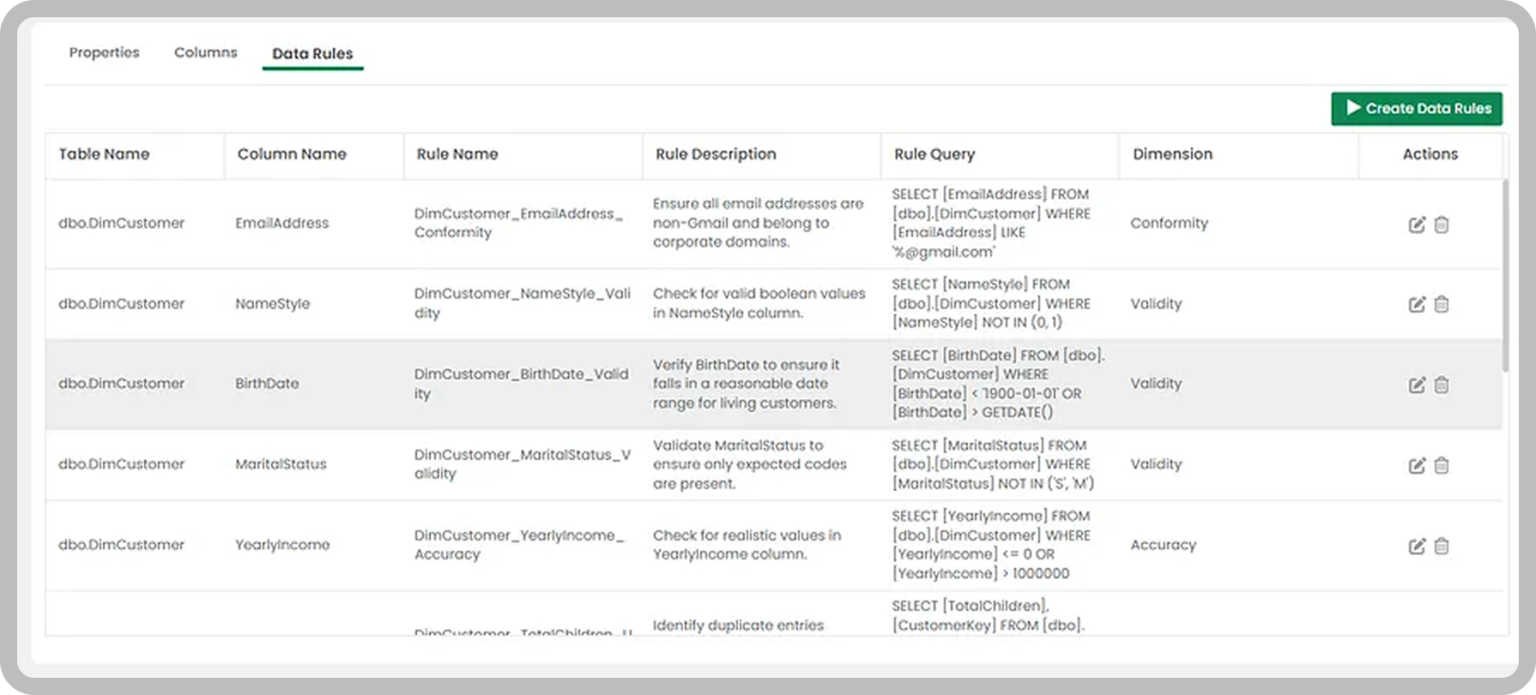
Step 8: Review AI-generated rules before execution
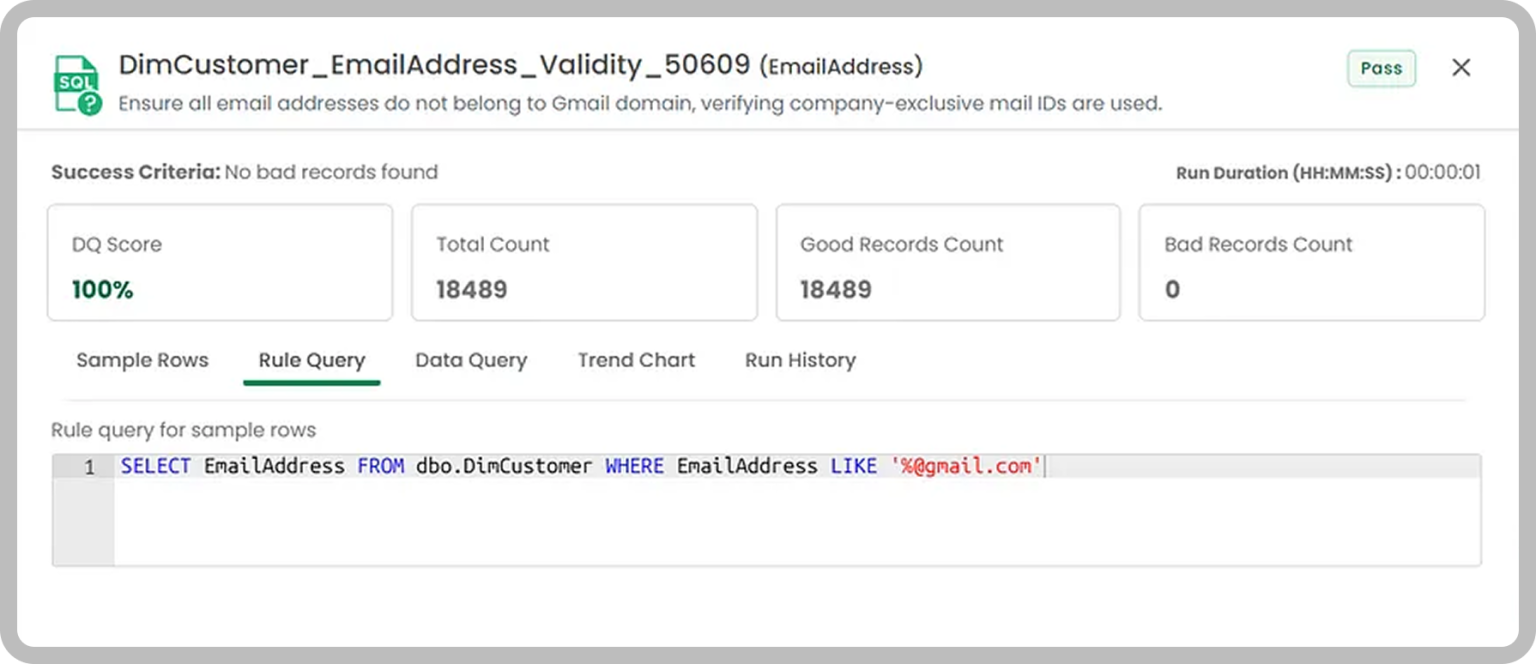
AI-generated rules typically include rule names, descriptions, mapped quality dimensions, and SQL logic that identifies bad records according to the chosen success criteria. Review these rules before running them to ensure they align with internal standards and domain expectations.
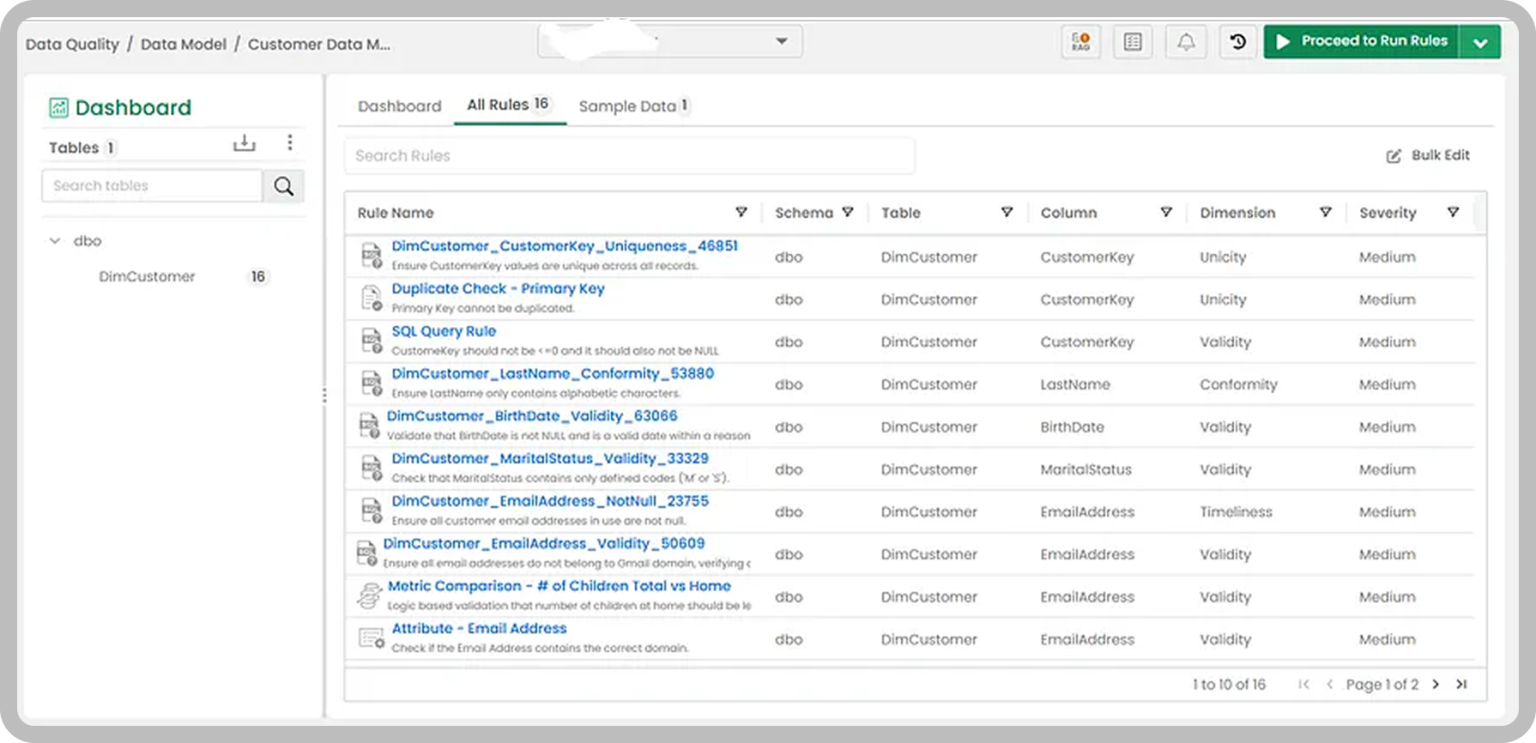
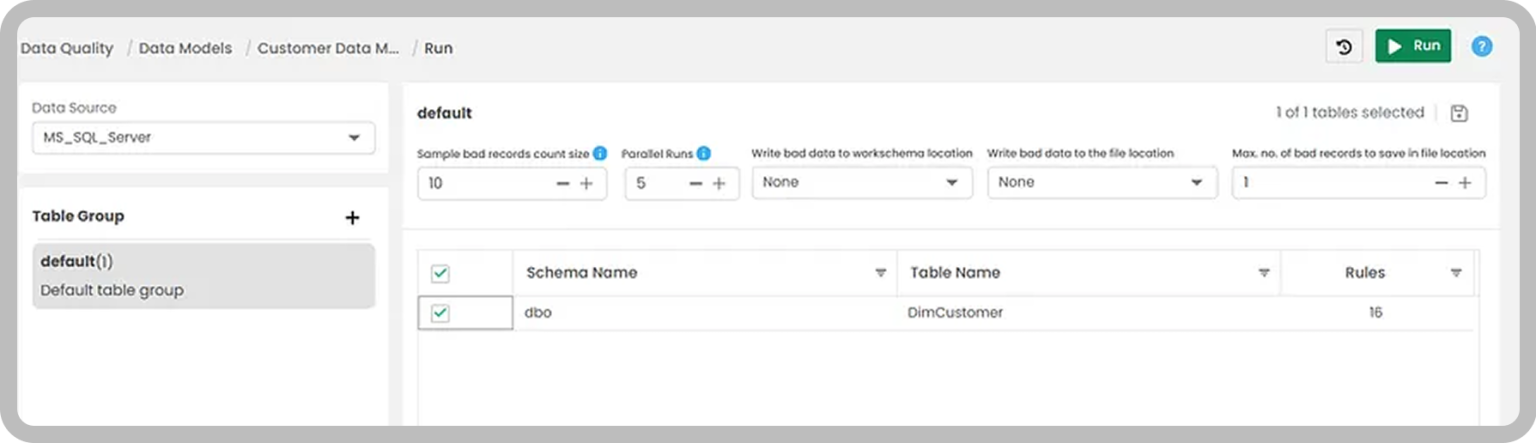
Step 9: Configure and run validations
Before execution, configure how the run should behave, including where to store bad records, parallel execution settings, and sampling limits for captured bad data.
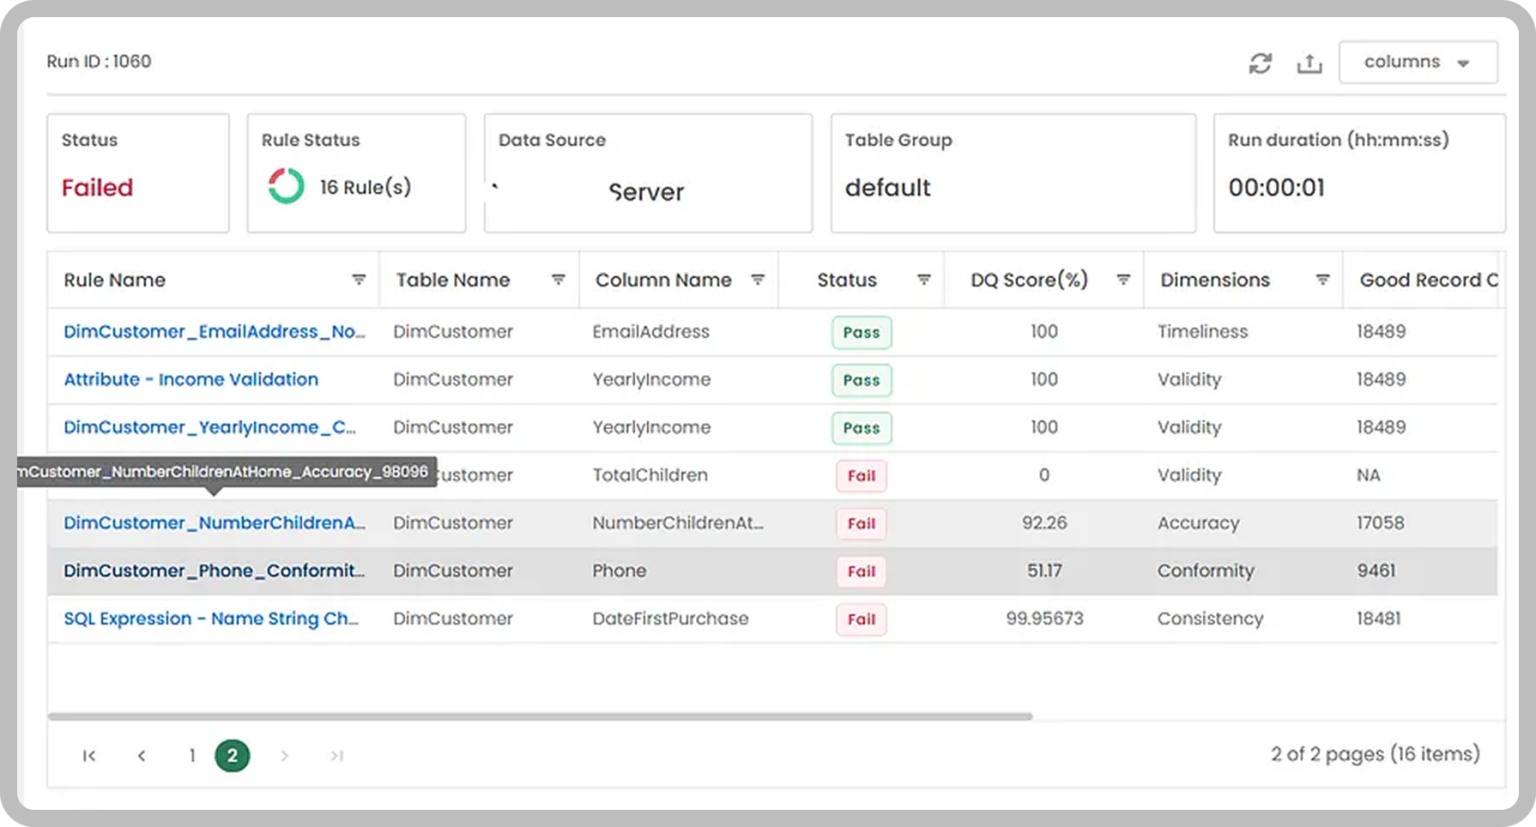
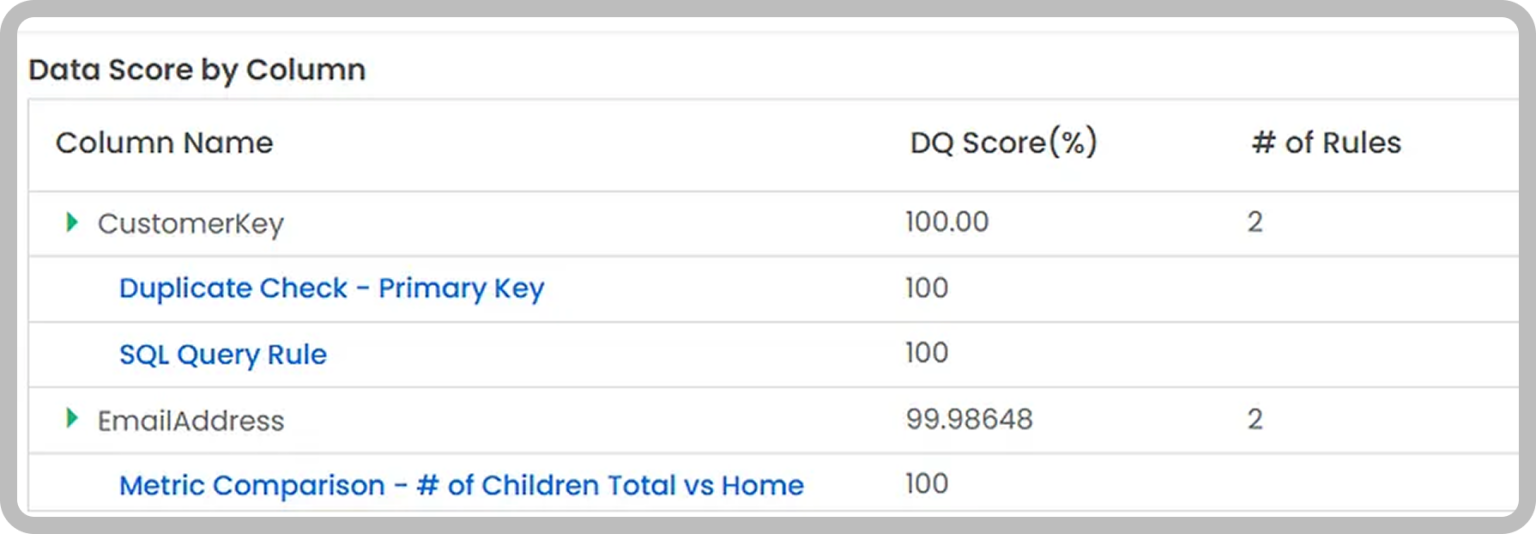
Step 10: Interpret results and prioritize remediation
After execution, results can be reviewed across multiple levels, including:
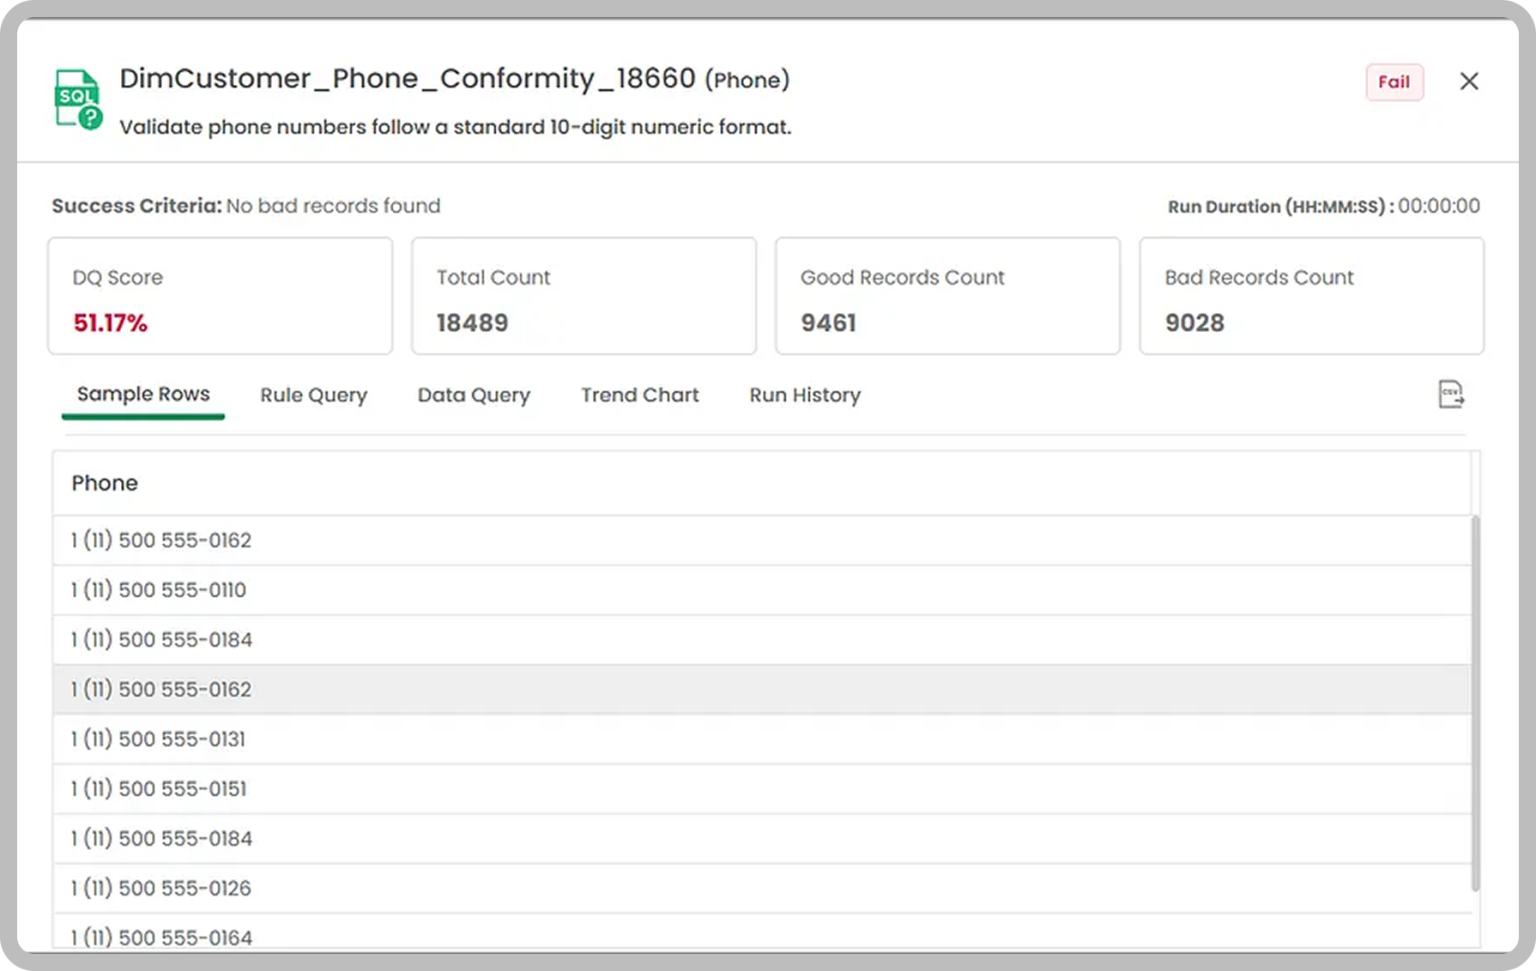
- Column-wise DQ score based on executed rules
- Rule-level pass or fail outcomes
- Sample bad records for investigation
- Summary view across rules and columns
Work through the results top-down: start with the high-level scoring view, then review one passing rule and one failing rule, and close with the overall summary.
How can teams operationalize AI-generated data quality rules in production?
To operationalize this at enterprise scale, standardize how rules are generated, reviewed and gated:
- Standardize prompts for repeatable rule generation across datasets
- Maintain domain prompts in a shared repository per business domain
- Add a review workflow for AI-generated rules, especially for cross-table logic
- Track DQ score trends and define thresholds for release gates Integrate validation runs into pipeline schedules for continuous monitoring
- Integrate validation runs into pipeline schedules for continuous monitoring
Conclusion
Microsoft Fabric enables fast analytics and AI experiences, but reliable outcomes depend on trustworthy data. Datagaps supports Fabric data quality workflows by helping teams generate rules faster, execute validations consistently, and interpret results with actionable detail. This reduces risk, improves reliability, and helps scale data quality practices across teams and environments.
Frequently Asked Questions
How does Datagaps generate data quality rules for Microsoft Fabric tables?
Datagaps generates rules through the AI-assisted mode of its Data Rules Wizard. You select the Fabric table and columns, define success criteria and severity, and provide a generic prompt plus a domain prompt. Datagaps then returns rule suggestions with rule names, descriptions, mapped quality dimensions and SQL logic that identifies bad records.
What data quality checks are typical for a Microsoft Fabric gold layer?
Common checks include numeric constraints such as revenue greater than zero, format checks such as valid email patterns, null checks for required attributes, uniqueness checks to prevent duplicate keys, and cross-table consistency checks that reconcile datasets. A gold layer often holds dozens of tables with dozens of columns each, which is why manual implementation becomes hard to manage.
Should AI-generated data quality rules be reviewed before they run?
Yes. AI-generated rules should be reviewed before execution to confirm they align with internal standards and domain expectations. Review covers the rule name, description, mapped dimension and SQL logic. For production adoption, add a formal review workflow, especially for cross-table logic, and keep domain prompts in a shared repository per business domain.
What can you configure before running data quality validations on Fabric data?
Before execution, you configure how the run behaves: where bad records should be stored, parallel execution settings, and sampling limits for the bad data that is captured. These settings are applied to the rules managed centrally within the data model, so validations run consistently each time they are triggered.
How do you interpret Datagaps data quality results for Microsoft Fabric?
Results are reviewed at several levels: a column-wise DQ score based on executed rules, rule-level pass or fail outcomes, sample bad records for investigation, and a summary across rules, columns and dimensions. Start with the high-level scoring view, then examine a passing and a failing rule, and finish with the overall run summary.

RajMohan Achanta
Associate Product Manager, Datagaps
Associate Product Manager at Datagaps. Shapes the product experience across ETL Validator, BI Validator, and Data Quality Monitor.

Avinash Keshri
Head, Product Marketing
Head of Product Marketing at Datagaps and IIM Bangalore alumnus. 13+ years of experience in commercializing AI and data platforms across global markets.