DEFINITION The AI Data Trust Score (ADTS) measures whether enterprise data can be understood, validated, traced, governed, and safely consumed by an AI system. It goes beyond data quality by evaluating six dimensions: Data Quality, Semantic Readiness, Freshness, Lineage, Governance, and Schema Stability — each scored and weighted by the AI use case.
Key Takeaways
- The AI Data Trust Score (ADTS) is the single metric that tells organizations whether their data is truly AI-ready — not just high-quality.
- A 100% DQ score can still mean 0% AI readiness if the AI system cannot interpret, trace, or safely consume the data.
- ADTS evaluates six dimensions: Data Quality + Semantic Readiness + Freshness + Lineage + Governance + Schema Stability.
- The formula: ADTS = Σ(wᵢ × Sᵢ) — each dimension scored 0–100, weighted by the AI use case, evaluated with per-dimension thresholds.
- Datagaps DataOps Suite operationalizes multiple ADTS dimensions with automated DQ scoring, AI-generated metadata, lineage, catalog, and pipeline monitoring.
Every enterprise deploying AI faces the same blind spot: data that scores well on quality checks but fails in production AI systems. In a previous article, we established that a DQ score must be evaluated against use-case-specific thresholds. That framework remains essential. But it assumes the DQ score itself captures everything AI needs from data. It does not.
This article introduces the AI Data Trust Score (ADTS) — a six-dimension composite metric that goes beyond data quality to measure whether enterprise data is truly ready for AI consumption. The ADTS is designed to be calculated, tracked, diagnosed, and operationalized — not just displayed on a dashboard.
THE PROBLEM A dataset can score 100% on data quality and still be unusable by AI. The DQ score tells you the data is correct. It does not tell you the data is trustworthy for what AI is about to do with it.
Consider a simple dataset with four columns: customer_id, REV_AMT, STATUS, and LAST_DT. Every value is populated. The datatypes are correct. Every business rule passes. The data quality score is 100%.
Now ask an AI system: what does REV_AMT mean? Is it gross revenue, net revenue, or revenue after refunds? Is it in USD or INR? Is STATUS = A indicating Active, Approved, or Archived? At what level of granularity — customer, transaction, or monthly aggregate?

The data is not wrong. It simply lacks the context an AI system requires to use it reliably. This is precisely the gap the AI Data Trust Score is designed to quantify — the distance between data that passes quality checks and data an AI system can actually trust.
What Is the AI Data Trust Score?
The AI Data Trust Score (ADTS) is a composite enterprise metric that answers a question no DQ score can: is this data trustworthy enough for what AI is about to do with it?
Traditional data quality evaluates whether data is reliable — accurate, complete, valid, consistent. The ADTS extends this by also measuring whether data is understandable, traceable, current, governed, and structurally dependable for AI. It is built from six dimensions, each scored 0–100 and weighted by the AI use case:
- Data Quality — Is the underlying data reliable? Measured through completeness, accuracy, validity, consistency, uniqueness, and referential integrity.
- Semantic Readiness — Can AI understand what the data means? Measured through metadata completeness, column descriptions, business glossary coverage, and relationship documentation.
- Freshness — Is the data current enough for its intended use? Measured through last successful refresh, expected refresh frequency, ingestion latency, and pipeline failure rates.
- Lineage & Traceability — Can the organization explain where the data came from? Measured through source-to-target mappings, transformation lineage, and provenance documentation.
- Governance & Security — Can the data be safely used by AI? Measured through data classification, PII identification, access controls, masking, retention policies, and regulatory compliance.
- Schema Stability — Can AI depend on the data structure remaining predictable? Measured through schema drift frequency, datatype changes, breaking changes, and contract violations.
How Does Each Dimension Contribute to AI Data Trust?
Dimension 1: Data Quality
Data quality is the foundation — the dimension organizations already measure. The question is whether the underlying data is reliable, evaluated through completeness, accuracy, validity, consistency, uniqueness, referential integrity, and business-specific rules. In Datagaps DataOps Suite, these rules are executed automatically and scores are calculated across each dimension independently.
However, for AI Data Trust, the DQ score becomes one input among six. A 95% data quality score confirms the data passed its defined checks. It does not confirm that an AI system can interpret, contextualize, or safely consume that data.

Dimension 2: Semantic Readiness
This is the dimension most commonly overlooked in AI readiness assessments — and arguably the most consequential. Consider the difference between a column described as REV_AMT = Revenue amount versus REV_AMT = Net recognized revenue at transaction level, excluding taxes and refunded transactions. Currency: USD. Grain: one record per completed transaction.
The underlying values are identical. The DQ score is identical. But the amount of context available to an AI system — particularly Text-to-SQL agents, RAG systems, and analytical copilots — is fundamentally different. This is why metadata has become a critical enabler for AI: it provides the semantic layer that allows AI systems to reason about enterprise data, not just process it.
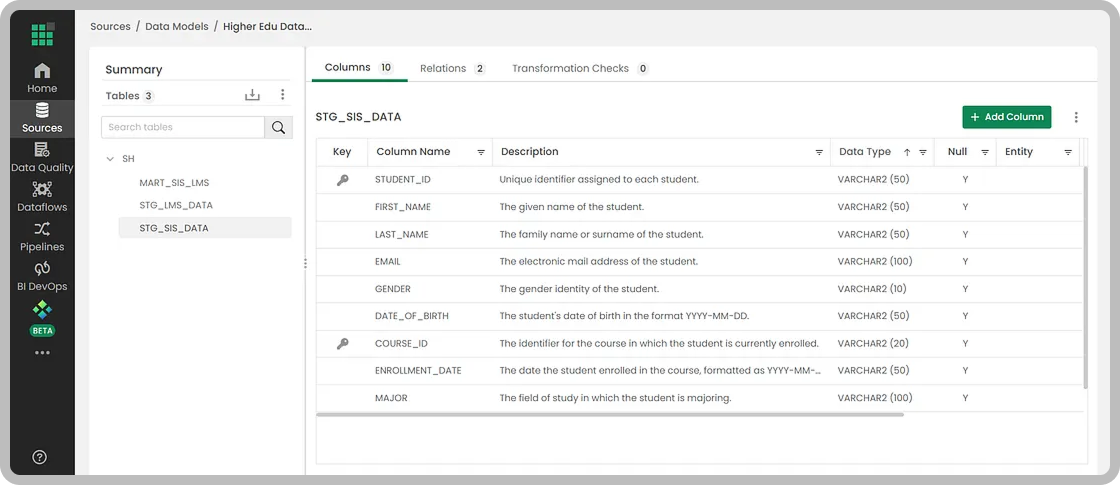
Datagaps DataOps Suite addresses this through AI-generated column descriptions within its Data Model interface. Each column receives a clear, contextual description — data type, nullability, and entity classification — providing the semantic foundation AI systems need.

Dimension 3: Freshness
Freshness is not an absolute measurement — it is relative to the AI use case. A dataset being old is not automatically problematic. A dataset being old when the use case requires current data is.
An AI-powered fraud detection system requires near-real-time data freshness. A historical trend analysis model may function well with monthly updates. The freshness dimension evaluates signals such as last successful refresh, expected refresh frequency, freshness SLA compliance, ingestion latency, pipeline failures, and time since last update.
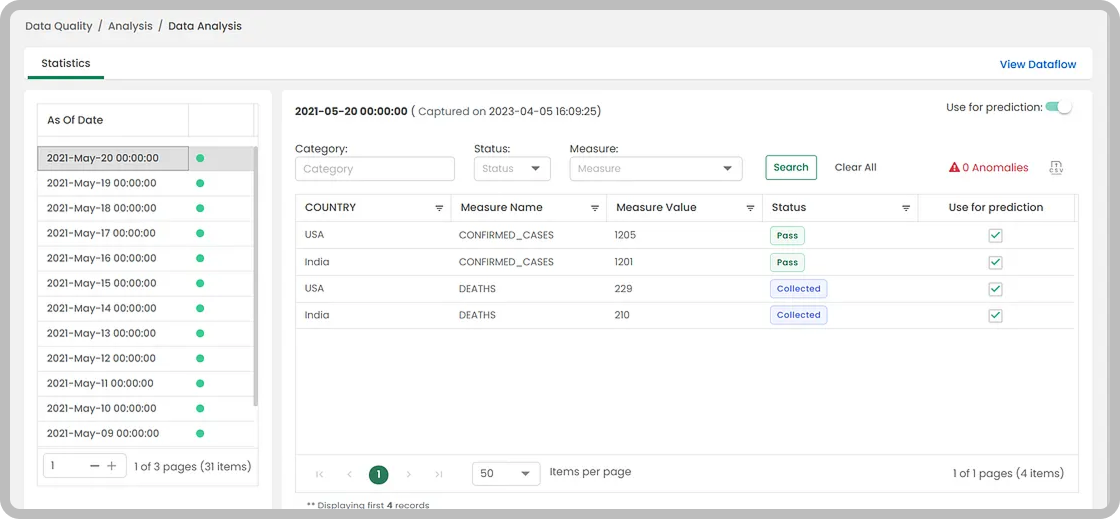
Different tables within the same dataset may require different freshness standards. A department reference table may not need immediate refresh, while a customer transactions table may require updates every few hours. Datagaps provides visibility into pipeline execution timing and freshness across all components.

Dimension 4: Lineage & Traceability
For AI systems to be auditable and explainable, organizations must be able to trace any AI-generated response back through the data chain: AI response → dataset → column → transformation → source table → source system.
Datagaps Data Lineage provides this capability, displaying source-to-target mappings with associated DQ scores at each stage. When an AI system produces an unexpected result, lineage enables the organization to identify whether the issue originated in source data, a transformation step, or a quality failure at a specific stage of the pipeline.

Dimension 5: Governance & Security
A dataset can score perfectly across quality, semantics, freshness, and lineage — and still be inappropriate for an AI use case if it contains sensitive customer information that the AI application is not authorized to access.
This is the distinction that separates quality from trust. Quality asks, “Is this data correct?” Trust also asks, “Can this data be safely used for what the AI system is about to do?”
The governance dimension evaluates data classification, PII and sensitive information identification, access controls, masking policies, authorization frameworks, retention requirements, regulatory compliance (SOC 2, HIPAA, GDPR, DPDP Act), and usage policies. Datagaps Catalog supports this through automated entity detection and CDM (Common Data Model) mapping, identifying columns that may contain sensitive data before it reaches an AI system.
This is the distinction that separates quality from trust. Quality asks, “Is this data correct?” Trust also asks, “Can this data be safely used for what the AI system is about to do?”

Dimension 6: Schema Stability
AI systems build assumptions about data structure. A Text-to-SQL agent generating queries against customer_id, customer_name, and customer_status will break silently if someone renames customer_status to status, changes a datatype, removes a column, or — most dangerously — keeps the same column name but changes what it means.
The goal is not to prevent schema changes. Enterprise systems change constantly. The goal is to make those changes observable and predictable so AI systems are not operating on stale structural assumptions. Datagaps Catalog tracks schema changes over time, surfacing metadata modifications, relationship changes, and column-level alterations.

How Is the AI Data Trust Score Calculated?
The ADTS follows a weighted composite formula that gives organizations a single, actionable number while preserving dimension-level diagnostics. Each of the six dimensions receives a score between 0 and 100, and the weights are set by the AI use case:
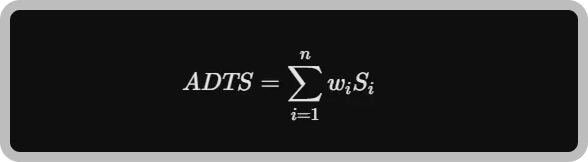
An enterprise where data freshness is critical might assign higher weight to that dimension. A regulated financial institution might emphasize governance and lineage. A Text-to-SQL deployment would weight semantic readiness and schema stability most heavily.
However, as established in the previous article, composite scores can hide critical failures. The same principle applies at the trust level:
| Dimension | Possible Evidence | Datagaps Capability |
|---|---|---|
| Data Quality | Automated DQ rules, profiling, validation | DQ Monitor — automated scoring across 6 dimensions |
| Semantic Readiness | Metadata completeness, definitions, glossary, relationships | DataOps Studio — AI-generated column descriptions |
| Freshness | Pipeline telemetry, refresh SLA, last successful load | Dataflows — pipeline monitoring and execution tracking |
| Lineage | Source-to-target mappings, transformation lineage | Data Lineage — visual lineage with DQ scores per stage |
| Governance | Classification, access controls, masking, policies | Catalog — entity detection, CDM mapping |
| Schema Stability | Schema monitoring, contract violations | Catalog — metadata change tracking |
The six dimensions of AI Data Trust with measurable evidence and corresponding Datagaps capabilities.

How Should Organizations Implement the AI Data Trust Score?
The real value of the ADTS is not the number on a dashboard — it is the diagnostic framework underneath. When the score is low, the dimension-level breakdown tells the organization exactly where to invest, eliminating guesswork:
- Low Data Quality score — The underlying data needs remediation. Datagaps stores and surfaces failed records for targeted correction.
- Low Semantic Readiness — The data may be accurate, but metadata is insufficient. AI-generated descriptions (available in Datagaps DataOps Studio) can accelerate metadata enrichment.
- Low Freshness — Pipeline monitoring and SLA enforcement are needed. Datagaps Dataflows provide execution timing and failure tracking.
- Low Lineage — Source-to-target documentation is incomplete. Datagaps Data Lineage provides visual lineage with quality scores at each stage.
- Low Governance — The issue may be access controls or classification, not data values. Datagaps Catalog supports entity detection and CDM mapping.
- Low Schema Stability — Structural changes are occurring without visibility.
Critically, passing the ADTS threshold today does not mean a dataset is AI-ready permanently. Schemas change, pipelines fail, definitions evolve, and access policies are updated. The AI Data Trust Score must be continuously monitored — not calculated once. Datagaps provides a centralized platform for tracking all six dimensions over time, turning the ADTS from a one-time assessment into an operational practice.
This is why a single number should never serve as the sole AI readiness decision-maker. At minimum, organizations need the overall DQ score and a separate view of quality across critical data elements and dimensions — precisely the granularity that platforms like Datagaps Data Quality Monitor are designed to deliver.
Frequently Asked Questions
What is an AI Data Trust Score?
The AI Data Trust Score (ADTS) is a composite metric that evaluates whether enterprise data is not only high-quality but also understandable, traceable, current, governed, and structurally stable for a specific AI use case. It extends traditional DQ scoring with five additional dimensions: semantic readiness, freshness, lineage, governance, and schema stability.
How is the AI Data Trust Score different from a Data Quality score?
A DQ score measures whether data conforms to defined quality rules — completeness, validity, consistency, etc. The ADTS includes DQ as one of six dimensions and adds whether AI can interpret the data (semantic readiness), whether the data is current (freshness), where it came from (lineage), whether it can be safely used (governance), and whether the structure is stable (schema stability).
Why can data pass all DQ checks and still be unsuitable for AI?
Data quality evaluates whether values are correct and complete. It does not evaluate whether an AI system has enough context to understand what those values mean, whether the data is fresh enough, whether it is authorized for AI consumption, or whether the schema has changed since the AI model was configured. These gaps are what the ADTS framework addresses.
How does Datagaps support the AI Data Trust framework?
Datagaps DataOps Suite provides capabilities across multiple ADTS dimensions: automated DQ scoring across six quality dimensions, AI-generated metadata descriptions for semantic readiness, pipeline monitoring for freshness, visual data lineage with quality scores, catalog-based entity detection for governance, and metadata change tracking for schema stability. Listed in Gartner’s Market Guide for DataOps Tools (2025) and Data Observability Tools (2026).
Can the AI Data Trust Score be automated?
Data quality scoring is already automated through tools like Datagaps. Other dimensions require a mix of automated signals (pipeline telemetry for freshness, schema monitoring for stability) and organizational assessments (governance policies, lineage documentation completeness). The ADTS framework provides a repeatable structure for combining both types of evidence.
How should organizations weight the six dimensions?
Weights should reflect the AI use case. A Text-to-SQL agent would weight semantic readiness and schema stability heavily. A fraud detection system would prioritize freshness and data quality. A regulated financial model would emphasize governance and lineage. There is no universal weighting — the framework is designed to be adapted per use case.

RajMohan Achanta
Associate Product Manager, Datagaps
Associate Product Manager at Datagaps. Shapes the product experience across ETL Validator, BI Validator, and Data Quality Monitor.

Avinash Keshri
Head, Product Marketing
Head of Product Marketing at Datagaps and IIM Bangalore alumnus. 13+ years of experience in commercializing AI and data platforms across global markets.