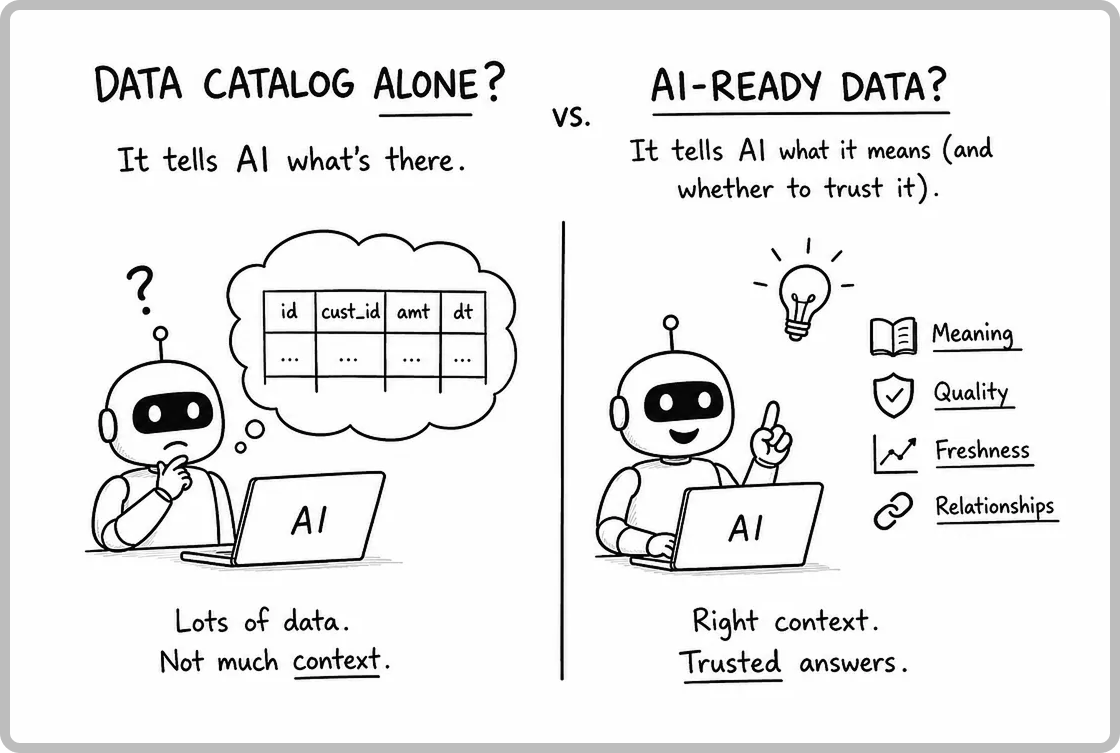
AI-ready data is enterprise data that has been profiled, validated, described, and continuously monitored — so AI systems can consume it with confidence. A data catalog alone tells you what exists. AI-ready data ensures what exists is accurate, meaningful, and trustworthy enough to power production AI at scale.
Key Takeaways
- A data catalog documents metadata but can’t verify whether the underlying data is correct.
- AI-ready data requires continuous quality validation layered on top of cataloging.
- AI-generated column descriptions are now critical inputs for Text-to-SQL, RAG, and copilot systems.
- The top-ranked BIRD Benchmark solution proves that data profiling and enriched metadata outperform better models.
- Datagaps DataOps Suite handles catalog, profiling, quality scoring, and AI-generated descriptions in one platform.
The AI Readiness Problem in 2026
Enterprises aren’t debating whether AI matters anymore. They’ve moved well beyond that. Over the last couple of years, organizations have aggressively shifted toward implementation — building AI solutions both internally and for their enterprise clients.
But there’s a meaningful gap between wanting to deploy AI and actually being ready for it. The critical question facing data leaders today isn’t which model to choose. It’s whether the data feeding those models is prepared for AI consumption.
The numbers make this clear. According to Forrester (2026), 73% of B2B buyers now use AI tools during vendor research and technical evaluation. The models themselves are mature enough. The bottleneck has shifted entirely to data quality and context.
Being AI-ready means your organization can confidently expose its data to AI systems at scale — knowing that data is accurate, governed, and described well enough to generate reliable outputs. That’s a much higher bar than most enterprises realize.
Two Types of Enterprise Data, Two Different Challenges
When we talk about making enterprise data AI-ready, it helps to separate the problem into two parts — because each type of data needs a fundamentally different approach.
The first is unstructured data — implementation documents, product documentation, API docs, knowledge bases, and similar textual information. AI is already quite good at understanding well-written text. If this information is documented properly and managed well, you can start building AI use cases on top of it.
The industry is actively working on this side of the problem. Google, for example, proposed its Open Knowledge Format (OKF) in June 2026 — a structured markdown-based approach for organizing internal knowledge so that AI agents can consume it effectively. It’s not a product they’re selling. It’s a recommended format for structuring your internal knowledge base in a way that works for both humans and AI systems.

But OKF only addresses the unstructured side of the problem. It helps document databases, business logic, and definitions in a structured way — but it doesn’t solve the challenge of structured data at scale.
The second — and harder — part is structured data. The tables, columns, and rows sitting in your databases. You obviously can’t pass millions of database rows to an LLM as part of a prompt. So how do you help AI understand your structured data well enough to generate accurate SQL, power dashboards, or drive automated decisions?
The most common answer is a data catalog. But that answer is incomplete.
What a Data Catalog Does Well
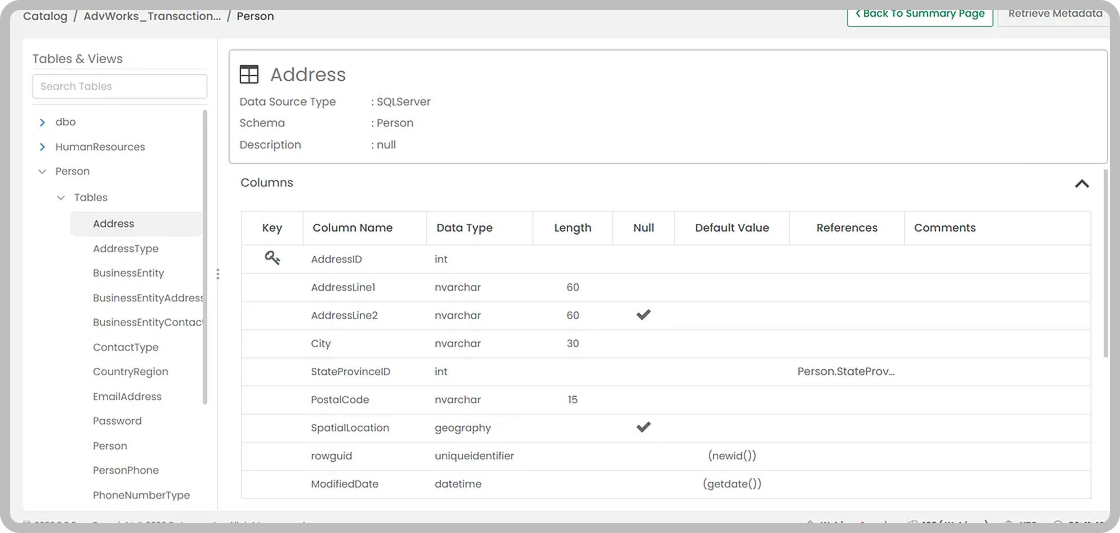
A data catalog combines and aggregates all the metadata — the “data about data” — so users can easily discover, understand, evaluate, and trust various resources like databases, tables, reports, and dashboards across scattered systems.

You should also be able to get a table-level and column-level view of the database. This helps in finding and tracking any changes to the schema over time. Tools like Datagaps offer this — you can automatically see what a table is about, its columns, relationships, and how they exist within the current database through its Catalog.

Where the Catalog Falls Short
The catalog definition above is almost complete. Notice that it talks about discovering, understanding, and evaluating data. But it deserves a closer look where it mentions “trust.”
You cannot build trust solely based on metadata. Trust is built on the data itself.
Metadata tells you what the data is supposed to represent. It does not tell you whether the underlying data is actually correct. A beautifully documented table can still contain duplicate records, missing values, broken calculations, or stale data.
If you have accurate data flowing through your pipelines at every stage, that’s when you can actually trust your system — and any AI application, report, dashboard, or BI tool that consumes data from that database.
So a data catalog alone is not sufficient. What else is needed?
Validated data — and a system that continuously validates it whenever new data arrives.
What AI Actually Needs: Quality Validation at Scale
You need quality checks that ensure whatever exists in your systems matches business expectations and is reliable enough for data-driven decisions.
That means a Data Quality dashboard showing how every table contributes to an overall quality score. You should have dedicated rules evaluating data across different quality dimensions — accuracy, completeness, conformity, consistency, timeliness — and your overall score should clearly reflect how each dataset contributes to the health of your data ecosystem.
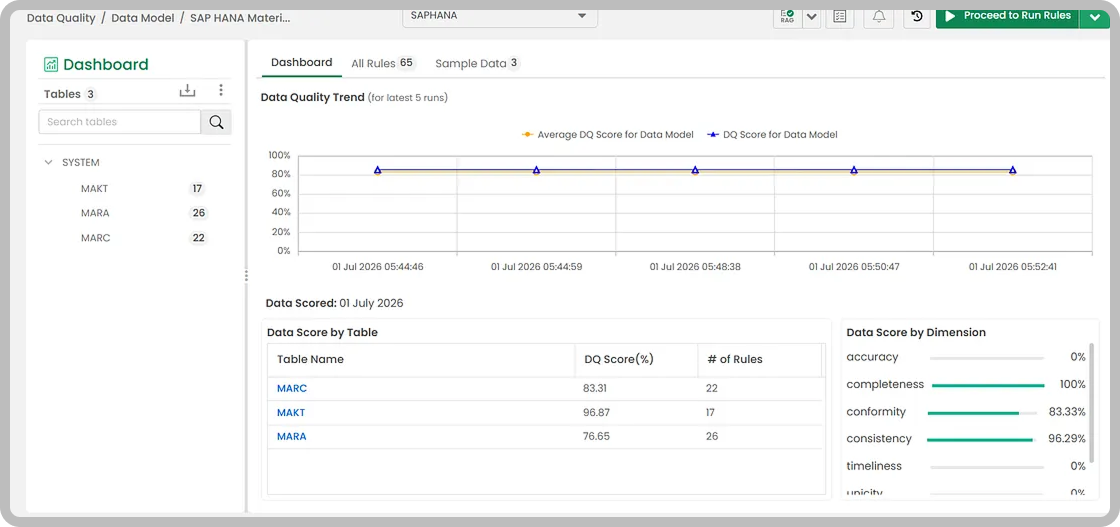
It shouldn’t stop at the table level. You should also be able to drill down to individual columns and understand exactly which columns are impacting the overall Data Quality score.

For example, while setting up governance and data cataloging, you may discover that certain columns must never contain duplicate or NULL values. Maybe another column should only contain values from a predefined set of categories. Or perhaps you have domain-specific business rules that must always hold true. These are business expectations — the rules you’ve defined.
But how do you execute those rules consistently? This is exactly where Datagaps DataOps Suite comes in. You need automated quality checks and detailed reports showing exactly how much of your data violates each rule. More importantly, you need to ensure that only validated data flows into your Gold layer or BI layer.

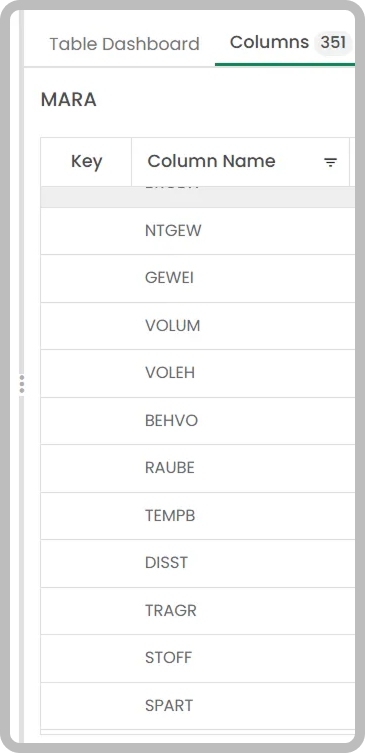
And we’re not talking about small datasets here. We’re talking about enterprise-scale environments where manually validating data is practically impossible. Imagine a table with 300+ columns. You cannot manually validate data at that scale. You need automation. And even defining quality rules across hundreds of tables manually isn’t practical anymore. You need AI there as well.
So Does This Make the Data AI-Ready?
The answer is yes and no.
Yes — because now we know that the data, or the context, we provide to AI is correct, validated, and reliable enough to support data-driven decisions. We can finally trust that data. That’s exactly what Datagaps helps with. Governance, Metadata Scanning, Data Profiling, and most importantly, Data Quality — all of these capabilities can be managed from a single platform.
No — because AI still needs more information to truly understand your database. AI is exceptionally good at interpreting language. You can certainly provide column names as context while asking it to generate SQL queries. But if we provide richer context that explains what each column actually represents and what kind of data it contains, that’s when we can truly call it an AI-ready data catalog.
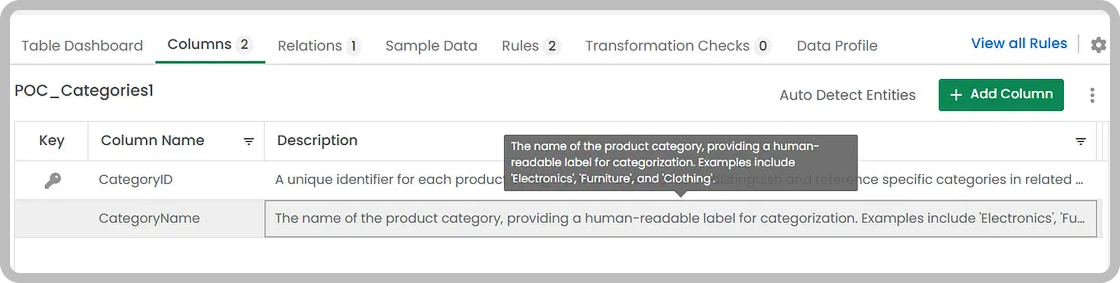
That’s where column descriptions come into the picture. Descriptions aren’t just documentation anymore. They have become one of the primary inputs to enterprise AI systems. Metadata is no longer written for humans. It’s increasingly written for AI.
Whether you’re building a Text-to-SQL system, an enterprise search solution, a RAG application, or an AI copilot, these descriptions help the model understand business meaning that column names alone can never communicate.
This isn’t useful only for AI, either. It’s equally valuable for any new team member joining your organization. They usually spend days understanding the database, learning business terminology, and figuring out what every column actually represents. In the age of AI, it would be inefficient if we didn’t make this process significantly easier.
Datagaps helps here through AI-generated descriptions for tables and columns. These descriptions are then used while generating SQL queries within DataOps, creating data quality rules, and building domain-specific validations involving multiple columns and complex SQL statements.
Does Research Back This Up?
One of the most common AI use cases for structured data has been generating SQL queries. Models today are powerful enough to write SQL of almost any complexity. What they still lack is context.
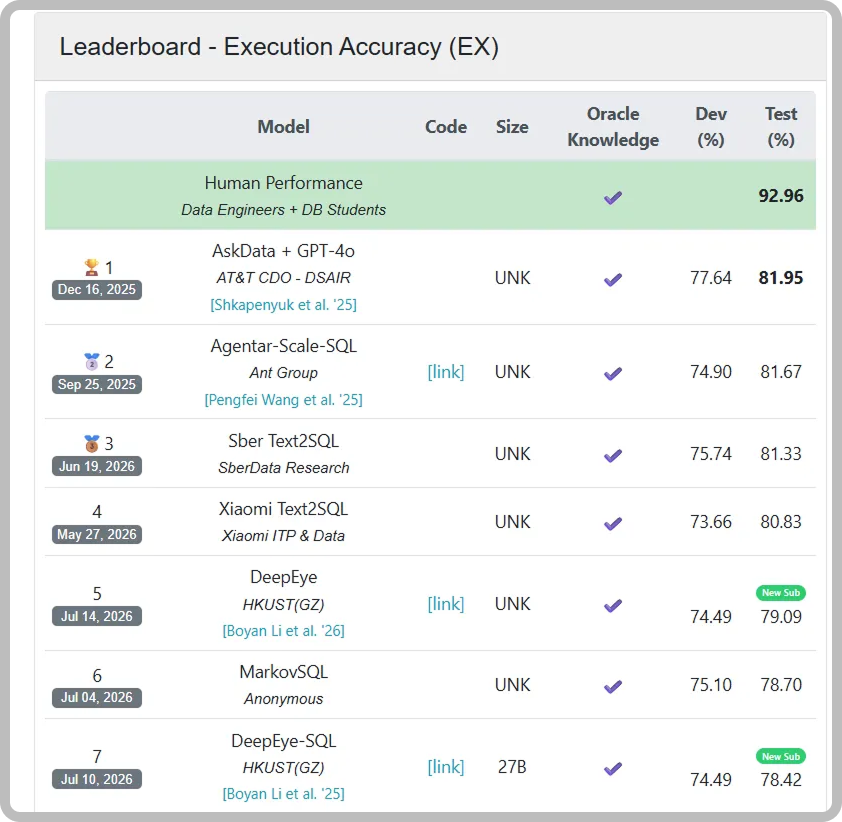
Every enterprise has its own abbreviations, business terminology, table names, and domain-specific concepts that are unique to them. The BIRD Benchmark — one of the leading benchmarks for Text-to-SQL systems — evaluates exactly this problem. It compares different AI solutions to determine whether they can generate enterprise-grade SQL queries for real-world databases.
Here’s what’s surprising: the top-ranked solution on this benchmark doesn’t even use the best language model. Many research papers from 2026 have still failed to outperform its approach. The issue isn’t really the model. It’s how we link our schema and provide the right context to the model.
The paper — Automatic Metadata Extraction for Text-to-SQL — follows three steps:
First, Perform Data Profiling — profile everything related to the data: NULL values, data types, minimum and maximum values, value lengths, distributions, and more. If your underlying data is incorrect, you’re already starting with the wrong foundation.
Second, Generate Descriptions — generate both short and detailed descriptions using the data profile created in the first step. If your data is accurate, the generated descriptions are naturally much more accurate. These descriptions are then converted into embeddings, enabling semantic search over your enterprise metadata.
Third, Create an LSH Index — build a locality-sensitive hashing index over the most important distinct values so the system can efficiently retrieve literals based on the user’s query.
This approach has remained one of the top-performing solutions for over a year. It pushes one very simple idea:
The better your data is, the better the metadata you can generate. The better your metadata is, the better context you can provide to AI. And the better the context, the better your AI solutions will perform. Both your metadata and your data need to be accurate and continuously validated.
The paper doesn’t start by generating descriptions. It first profiles the data. That’s exactly why tools like Datagaps DataOps Suite execute continuous Data Quality checks. They help ensure that the context reaching AI systems is not only descriptive but also trustworthy, making your enterprise significantly more AI-ready.

Frequently Asked Questions
What's the difference between a data catalog and AI-ready data?
A data catalog documents metadata — table structures, column types, and relationships. AI-ready data goes further by validating that the underlying data is accurate, enriching it with AI-generated descriptions, and continuously monitoring quality. Datagaps DataOps Suite provides all of these capabilities in a single platform.
Why does data quality matter for enterprise AI?
AI outputs are only as good as the context they receive. If your data contains duplicates, NULL values, or broken business rules, the AI outputs — whether SQL queries, reports, or automated decisions — will be unreliable. Continuous data quality validation ensures only trusted data reaches your AI systems.
How does Datagaps help enterprises become AI-ready?
Datagaps DataOps Suite combines data cataloging, automated data profiling, quality rule execution, scoring dashboards, and AI-generated column descriptions. This end-to-end approach ensures structured data is not just documented but validated and enriched for AI consumption.
What is the BIRD Benchmark and why does it matter?
BIRD is the leading benchmark for evaluating Text-to-SQL systems on real-world enterprise databases. The top-ranked solution demonstrates that data profiling and enriched metadata — not just a more powerful model — drive accuracy. Datagaps provides exactly these profiling and description capabilities.
Can Datagaps generate column descriptions automatically?
Yes. Datagaps uses AI to automatically generate business-context descriptions for tables and columns. These descriptions serve as primary inputs to Text-to-SQL engines, RAG applications, and AI copilots — helping models understand what each column represents beyond just its name.
How long does it take to set up data quality monitoring with Datagaps?
Datagaps offers a no-code interface for defining and executing data quality rules. Setup typically takes hours, not weeks. Automated profiling scans your database structure, and AI-assisted rule generation helps define quality checks across hundreds of tables without manual configuration.

RajMohan Achanta
Associate Product Manager, Datagaps
Associate Product Manager at Datagaps. Shapes the product experience across ETL Validator, BI Validator, and Data Quality Monitor.

Avinash Keshri
Head, Product Marketing
Head of Product Marketing at Datagaps and IIM Bangalore alumnus. 13+ years of experience in commercializing AI and data platforms across global markets.